

Summarize this article with AI
Your Crawl Stats chart has dipped, a priority page still says "Discovered - currently not indexed", or something calling itself Googlebot keeps hitting your login page. Search Console will tell you Google's version, in summary form. The access logs on your server have the raw story, one request at a time.
This log file analysis SEO guide runs from the first export all the way to the developer ticket. Along the way: where logs live and how long hosts keep them, why the totals never match Crawl Stats, command-line summaries you can run today, matching log evidence to Page indexing statuses, and the AI crawlers now turning up next to Googlebot.
Log file analysis for SEO: what logs show and what they miss
Log file analysis for SEO means reading your server's access logs to see which URLs search engine bots requested, when they made those requests, and which HTTP status codes they received.1 Google says Search Console doesn't provide a crawl history you can filter by URL or path and points you to your site logs to check whether specific URLs were crawled.
What log files add to a link crawler and Crawl Stats:
- Real crawl behavior over time, not a single snapshot1
- Requests to URLs your link crawl never finds, such as orphan pages and old URLs Google still remembers
- Requests from bots outside Google, including AI crawlers and anything borrowing Googlebot's name
Logs miss things too. An access log records the requests that server processed under its logging configuration, so CDN cache hits that never reach the origin aren't in it. Even AWS describes its Application Load Balancer and CloudFront access logs as best effort. So when a request isn't in an incomplete export, the export itself might be the gap. It's worth ruling that out before anyone files it as a crawling problem.
Key takeaways:
- Never crawled, or just outside the export? Dates, hostnames and edge versus origin decide that.
- Verify the IP before you treat a "Googlebot" user agent as Google.2
- Grouping requests by site section, path and HTTP status code tells you where to dig.
- Line the logs up against Page indexing and URL Inspection, and don't judge search performance until the fix is confirmed live.
| What you see | First check | Decision |
|---|---|---|
| An important page has no logged Googlebot visit | Export dates, hostname, edge coverage and verified bot filter | Investigate discovery after checking coverage |
| A page that should be accessible returns 5xx or 429 | Affected paths and timestamps | Prioritize server-side investigation |
| Removed pages return 404 or 410 | Whether removal was deliberate and links still point there | Keep the removal response; review stale links |
| A page returns 200 but is not indexed | Page indexing status, directives and canonical selection | Continue the indexing investigation |
| A spike claims to be Googlebot | Requesting IP verification | Separate verified Google traffic from unverified candidates |
How long log files stick around, and how to keep them
First question, before any analysis: how far back do your logs go? On some hosts that's days, not months, so plan the export around the window you actually have. Keep the original files and note the hostname, time zone and layer (edge or origin) for each one.
| Product or setup | Where to get logs | Coverage or retention to record |
|---|---|---|
| Debian's Apache or nginx packages | /var/log/apache2/access.log or /var/log/nginx/access.log, plus rotated files |
Rotated daily with 14 old files kept (about two weeks); check your server's logrotate settings |
| Kinsta | MyKinsta > Sites > your site > Logs, or SFTP | Logs are retained for up to four days |
| WP Engine Origin access logs | User Portal > environment > Logs > Access | View or download the most recent 1,500 requests |
| WP Engine Edge access logs | The same Access tab, CSV download | Up to 20 million requests from the past 72 hours |
| cPanel | Metrics > Raw Access | Download current raw logs; review archive and retention settings |
| Cloudflare Logpush | Configure a destination for the HTTP requests dataset | Exports logs without storage or search; cannot backfill missing history |
| AWS Application Load Balancer | Enable access logging to your S3 bucket | Disabled by default; best-effort request records |
| AWS CloudFront | Access log delivery | Best effort; an entry may not be delivered |
Since September 30, 2026, Cloudflare Logpush has been available on Free, Pro, Business and Enterprise plans with usage-based pricing, and Free, Pro and Business customers can turn it on themselves.3 Because Logpush can't backfill, set it up before you need the history.4 WP Engine LargeFS can offload Nginx access and error logs to your own S3 bucket through Support. For cPanel, review the options for archiving raw access logs and removing the previous month's archives before relying on retained history.
Ask the server owner whether conditional logging leaves gaps in the log data. Behind Cloudflare, distinguish EdgeResponseStatus from OriginResponseStatus: an origin value of 0 means no origin response was received and Cloudflare served the response at the edge.5 On a zone running Workers, a 0 can also come from a Workers subrequest made to the origin. If you have both edge and origin logs, count from one layer and use the other to investigate the same path, so one visit isn't counted twice.
Log files vs Crawl Stats: why the numbers don't match
Google Search Console's Crawl Stats report gives a Google-only overview of total requests, download size, average response time and host status. It is available for root-level properties: Domain properties or URL-prefix properties at the root. Its totals include most crawl requests, while the example URL lists are representative rather than exhaustive.6 Google adds that a site with fewer than a thousand pages shouldn't need the report or this level of crawl detail.
Use Crawl Stats for host-level changes and log file analysis for a path-by-path history. The table below explains why those datasets can disagree without either export being broken.
| Reason for a difference | What to account for |
|---|---|
| Origin export behind a CDN | Edge-served cache hits do not reach the origin |
| Conditional logging or best-effort delivery | The log source can omit requests |
| Crawl Stats example URLs | Absence from an example list does not mean Google did not request the page |
| Redirects | Crawl Stats counts each redirect hop as a request; client-side redirects are not counted |
| "Page could not be reached" | The request never reached the server, so it cannot appear in its logs |
| Unavailable robots.txt | Google can count crawls it would have made while the file was unavailable, without making those requests |
| Property and hostname scope | Match the property coverage to the servers and hostnames in your export |
| Reporting delay | Google says collected Search Console data should normally be available in two to three days |
For URL-level comparisons, match URL Inspection's "Last crawl" to the log timestamp. The log uses server time; "Last crawl" uses your local time. "Crawled as" shows the desktop or mobile crawler type.7 Record those differences in your audit notes before declaring a mismatch.
Read the access log format before choosing analysis tools
Check the format before you parse a log or import it into a tool, because the default depends on the server. Nginx and Debian's default Apache site configuration use Combined Log Format. Apache's stock configuration uses Common Log Format, which lacks the referrer and user-agent fields.
This constructed Combined-format example abbreviates the Googlebot Smartphone user agent for readability:
66.249.66.1 - - [02/Oct/2026:06:25:15 +0000] "GET /blog/example-post/ HTTP/1.1" 200 48211 "-" "Mozilla/5.0 (Linux; Android 6.0.1; Nexus 5X Build/MMB29P) ... Mobile Safari/537.36 (compatible; Googlebot/2.1; ...)"
| Field | Example | Use in the audit |
|---|---|---|
| Client IP | 66.249.66.1 |
Verify the requesting bot |
| Timestamp and offset | [02/Oct/2026:06:25:15 +0000] |
Compare crawl activity before and after a change |
| Request method, path and protocol | GET /blog/example-post/ HTTP/1.1 |
Identify what was requested; retain query strings |
| HTTP status code | 200 |
Group response patterns |
| Response size | 48211 |
Bytes returned; Apache %b uses - when there is no content |
| Referrer | "-" |
Referrer field in the record |
| User agent | Abbreviated Smartphone string | Claimed client identity, to check against the IP |
Choose a spreadsheet for a focused URL comparison, the command line for repeatable summaries, or a log analyzer for recurring imports and grouped views. For manual log analysis, save the filters alongside the findings so you can repeat the process.
Before you commit to a log analyzer, test it on a sample of your own logs: it should parse your format and keep the query string and user agent. Keep human visits in a separate view from verified bot traffic. Comparing the two shows pages people use that bots rarely request, and the reverse.
How to confirm a Googlebot hit isn't spoofed
A user-agent string claiming to be Googlebot proves nothing by itself.2 Verify the source IP using reverse and forward DNS, or match it against Google's published crawler IP ranges before assigning the request to Googlebot.8
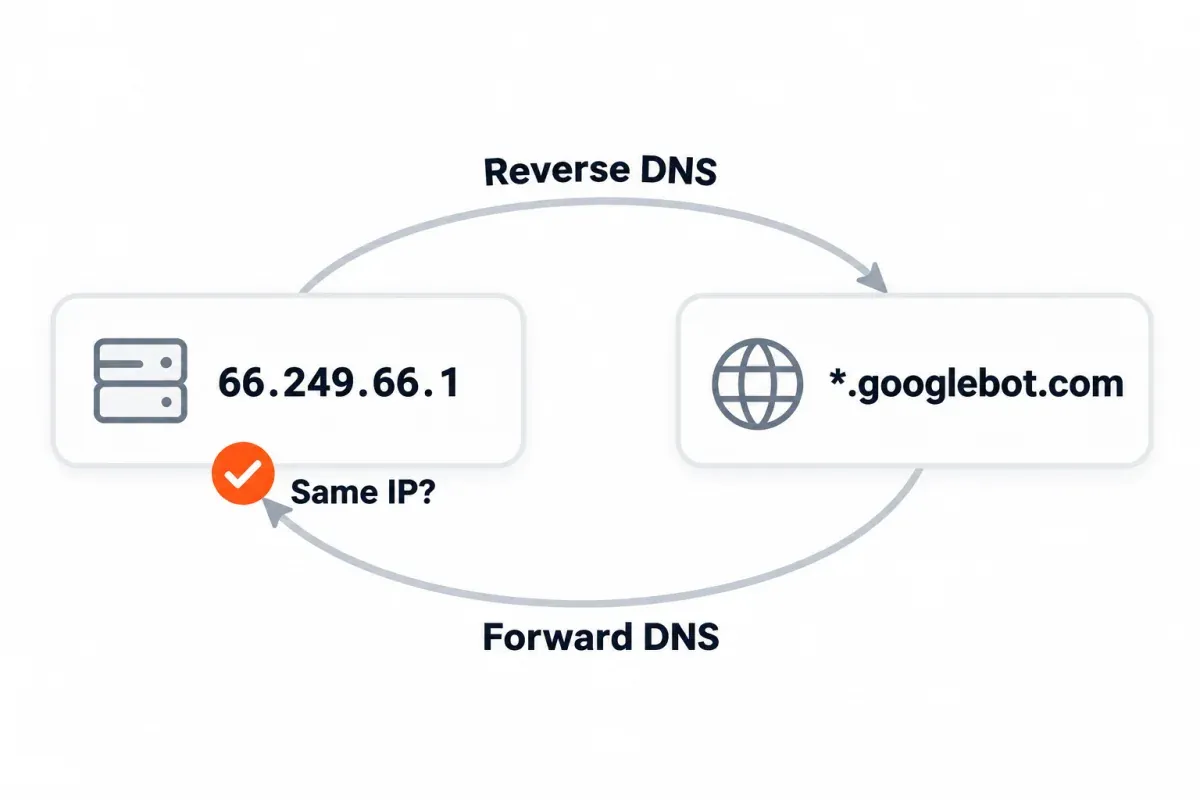
- Step one is a reverse DNS lookup on the client IP. For Googlebot and other common Google crawlers, check the
googlebot.comdomain, includinggeo.googlebot.comhostnames.8 - Run a forward DNS lookup on that hostname and confirm it resolves back to the same IP address you started with.8
Google's broader verification procedure also accepts google.com and googleusercontent.com for other Google crawlers and fetchers.8 Do not treat those groups as interchangeable with Googlebot. Google's own documentation example passes the test: when I checked it in October 2026, 66.249.66.1 resolved to crawl-66-249-66-1.googlebot.com, and that hostname resolved back to 66.249.66.1.
For Bingbot, verification uses a reverse lookup ending in search.msn.com followed by a forward lookup to the same IP, or Bing's verification tool or IP list.
Analyze your logs from the command line
These commands give you a first pass on an exported Combined-format access.log with no tool to install. The first command (or the second, for rotated and gzipped files) keeps only the lines whose user-agent field claims Googlebot: split on double quotes, a Combined line puts the user agent in field six, so "Googlebot" in a path or referrer doesn't count. The rest split on spaces: client IP in field one, path in field seven and HTTP status code in field nine. Adapt them for a custom format; a Common-format file has no user agent to filter on.1
I tested them on a sample Combined-format log with the awk that ships with macOS. Investigate malformed lines separately. The filter finds requests claiming Googlebot, including spoofers and Googlebot-Image or Googlebot-Video; it misses Google-InspectionTool, GoogleOther and Storebot-Google. Verify the candidate IPs before using the summaries as Googlebot crawl data.
# Keep requests whose user agent claims Googlebot
awk -F'"' '$6 ~ /Googlebot/' access.log > googlebot-candidates.log

# Same filter across plain and gzipped rotations (access.log, access.log.1, access.log.2.gz...)
gzip -dcf access.log* | awk -F'"' '$6 ~ /Googlebot/' > googlebot-candidates.log

# Candidate IPs to verify
awk '{print $1}' googlebot-candidates.log | sort | uniq -c | sort -rn

# HTTP status codes among candidate requests
awk '{print $9}' googlebot-candidates.log | sort | uniq -c | sort -rn

# Most-requested paths, including query strings
awk '{print $7}' googlebot-candidates.log | sort | uniq -c | sort -rn | head -20

# Requests to parameter URLs versus URLs without a query string
awk '{ if ($7 ~ /\?/) p++; else c++ } END { print "Requests to URLs with parameters:", p+0; print "Requests to URLs without:", c+0 }' googlebot-candidates.log

# Requests by site section and response code
awk '{ split($7, part, "/"); print "/" part[2], $9 }' googlebot-candidates.log | sort | uniq -c | sort -rn

# AI crawlers by name, matched in the user-agent field only (verify their IPs too)
awk -F'"' '{print $6}' access.log | grep -o -E 'GPTBot|OAI-SearchBot|ChatGPT-User|ClaudeBot|Claude-SearchBot|Claude-User|PerplexityBot|Perplexity-User|CCBot|Applebot' | sort | uniq -c | sort -rn
The counts are requests, not distinct URLs: a URL Googlebot fetched five times counts five times. The parameter share is a pointer for where to look next. It isn't a target percentage. And a query string, by itself, says nothing about whether the page belongs in search. Pull CSS, JavaScript and image requests apart from content requests. Keep a resource view anyway, since Google needs some of those files to render pages.
Turn log file analysis findings into actions
Log findings go into the backlog like any other technical SEO work. Important pages and server errors come first; crawl budget wasted on unnecessary URL inventory can wait its turn. When you look at crawl frequency, compare a section against a comparable baseline on your own site. Rare visits don't prove an internal-link problem, either. Crawl demand depends on perceived URL inventory, popularity and staleness.
Check crawl budget and rendering resources
Google's crawl budget guidance targets large sites with about one million or more unique pages changing weekly, sites with 10,000 or more pages changing daily, and sites with many URLs marked "Discovered - currently not indexed." Google's crawl budget guide calls its site-size thresholds rough estimates, not exact cutoffs.9 How much time crawl allocation deserves depends on where your site falls in that range.
| Pattern | Action to investigate | How to validate |
|---|---|---|
| Repeated filter or session-identifier requests | Separate useful search pages from unwanted combinations; review robots.txt and canonical rules | Compare requests for the affected patterns after deployment |
| Duplicate versions keep receiving requests | Consolidate duplicate signals; canonical tags may reduce non-canonical crawling over time | Check canonical selection and subsequent crawl activity |
| Unchanged content gets repeated full responses | Ask the developer to review ETag or Last-Modified support | Look for conditional requests and 304 responses where appropriate |
| Changed CSS or JavaScript appears stale when rendered | Review content fingerprinting, such as main.2bb85551.js |
Check that pages reference the changed resource URL |
Conditional caching works with Google through ETag or Last-Modified (ETag is the one Google recommends). Don't expect conditional headers on every attempt, though. When you do see a 304, the content hasn't changed. Rendering is a separate case. Google's Web Rendering Service may ignore caching headers, which is why Google suggests fingerprinted resource names.
And noindex won't stop crawling. Google still fetches the page first, then drops it from indexing. Blocking URLs does not automatically redirect the saved crawl budget to priority pages; Google says that shift depends on already reaching the site's crawl capacity limit.9 For unwanted filter combinations, review crawl controls separately from whether a canonical should consolidate duplicate content.
Triage errors and redirects by site section
Group codes by site section and exact path before assigning a ticket. Google says 5xx and 429 responses temporarily slow crawling, while 4xx responses other than 429 do not change the overall crawl rate.10 Leave server errors in place long enough and pages can fall out of the index.
| Log pattern | Investigation | Validation |
|---|---|---|
| A path alternates between 404 and 301 | Compare routing and redirect behavior at the logged times | Confirm the agreed response remains consistent |
| Several redirects precede the destination | Trace the route and shorten the chain | Confirm the old URL reaches the chosen destination directly |
| 404 or 410 on removed content | Review whether removal is deliberate and whether internal links are stale | Check the response and updated links |
| 401 or 403 on intended public content | Review authentication, access rules and bot verification | Test the public route and check subsequent verified requests |
| 5xx or 429 cluster | Give the developer affected paths and timestamps | Compare errors and response times after the server change |
Google's crawlers follow up to 10 redirect hops by default.10 Not sure which redirect fits the move? See 301 vs 302 redirects. A cluster of server errors calls for the "Server error (5xx)" investigation, with the log evidence beside it. When verified Googlebot requests receive a 403 or another 4xx response on public pages, the guides to "Blocked due to access forbidden (403)" and "Blocked due to other 4xx issue" cover the common causes.
Find orphan candidates and under-crawled pages
To discover orphan pages, match verified bot visits to a fresh crawl of internal links and your sitemap inventory. A log-only URL is an orphan candidate, but it can also be a removed page, a parameter variant or an old URL Google remembers. Google's Page indexing documentation says Google can find a page through a link from a known page or a sitemap.11
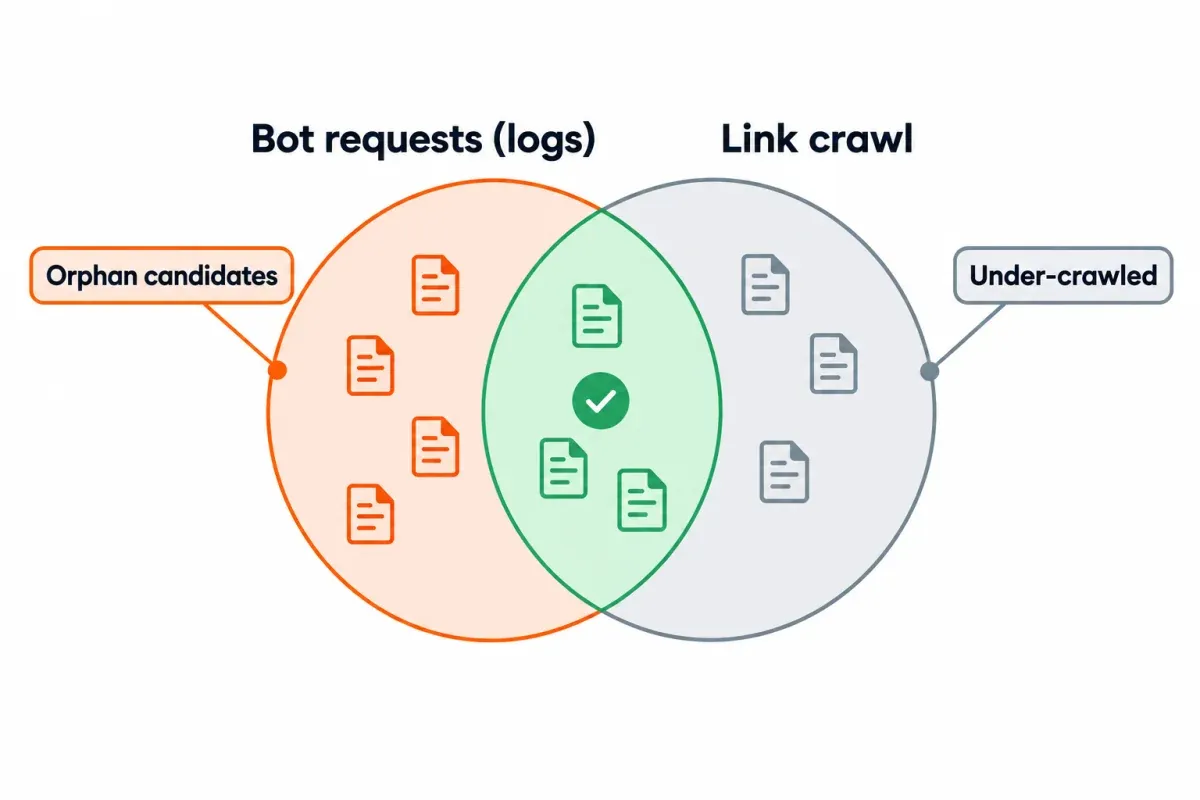
For a useful page missing from the link crawl, add standard crawlable links and review sitemap inclusion. For a linked page absent from the logs, check the export window, robots.txt and serving capacity before changing the content. Assess crawl frequency alongside similar pages instead of assigning a universal recrawl deadline.
Match crawl evidence to Search Console indexing statuses
A logged 200 confirms a successful fetch at that time. Google says that success does not guarantee indexing, so use it as evidence of access rather than a quality diagnosis.10 Check the exact Page indexing status before choosing the next investigation.
| Page indexing status | Log evidence to look for | Next check |
|---|---|---|
| "Crawled - currently not indexed" | Verified Googlebot requests, potentially with 200 responses | Review noindex, duplicates, canonical selection, rendered content and soft 404 symptoms |
| "Discovered - currently not indexed" | No Googlebot crawl corresponding to that status | Confirm log coverage, then check discovery and serving capacity |
| "Soft 404" | A 200 can accompany an empty or error-like page | Restore useful content, or return 404/410 for removed content |
| "URL blocked by robots.txt" | Googlebot fetches of /robots.txt, rather than requests to the disallowed page |
Check the rule and whether the block is deliberate |
| "Server error (5xx)" | Server-error responses on affected paths | Match the failure time to the host investigation |
| "Page with redirect" or "Redirect error" | Redirect responses on the route | Check the destination, loops and chain length |
With "Discovered - currently not indexed", Google knows the page exists but hasn't crawled it, so the last crawl date is blank. Spot a verified visit after that? Check the timestamps, because the report may be behind. "Crawled - currently not indexed" means Google crawled the page without indexing it, and Google says resubmitting that URL for crawling is unnecessary.11
For automatic crawls, Google's common crawlers respect robots.txt disallow rules, so repeated requests to a blocked path are not the expected evidence.8 If that file fails to return a valid response or a 404, Google can slow or stop crawling the site.6 So look at whether robots.txt is reachable, not just what's in it.
For one page, URL Inspection shows the indexed result. For bulk work, remember that the Page indexing tables show up to 1,000 example URLs, although the report totals cover the broader set.11 So a page missing from those examples could still have the issue.
AI crawlers: who shows up in the logs and who doesn't
Some AI bots collect for model training, some feed AI search, and some fetch only when a user asks. Sort them that way before any access rules get written. Their jobs aren't the same as a traditional search crawler's. And the name in a request proves nothing. Check the source IP against the ranges the vendor publishes. A 2026 arXiv preprint by Lopez-Fonseca and colleagues found that some AI assistants used generic user agents that complicated attribution.12
| Purpose | Agents | Documented role |
|---|---|---|
| Potential model training | GPTBot, ClaudeBot | Collect content that may contribute to model training |
| AI search | OAI-SearchBot, Claude-SearchBot, PerplexityBot | Support search results; PerplexityBot is not used for foundation-model training |
| User-triggered fetch | ChatGPT-User, Claude-User, Perplexity-User | Visit pages in response to user actions or questions |
| Open crawl dataset | CCBot | Collect data for Common Crawl's publicly accessible crawl repository |
| Apple search and possible training | Applebot | Supports search in Spotlight, Siri and Safari; data may also support foundation-model training |
You'll find crawler IP lists from OpenAI, Anthropic and Perplexity. Common Crawl and Apple have their own ways to verify, too. Allow or block? Let each crawler's documented purpose and the load you actually see in the logs make that call, and keep watching after.
Keep crawling, training and search visibility controls separate
Which control works depends on the bot. ChatGPT-User may not follow robots.txt rules at all, per OpenAI, and Perplexity says Perplexity-User generally ignores them. Anthropic's bots honor robots.txt, the company says, and even support Crawl-delay. Googlebot and Applebot don't.
You won't find Google-Extended or Applebot-Extended in your logs. They're robots.txt control tokens, not crawlers. Google-Extended controls Gemini training and grounding without affecting inclusion in Google Search. Applebot-Extended controls training use of data collected by Applebot.13
Google's AI features in Search use Googlebot. Search Console's Search generative AI control (Settings > Search generative AI), rolled out to all sites on August 31, 2026, covers AI Overviews, AI Mode and generative AI features in Google Discover.14 The control governs appearance in those features, while Google-Extended addresses training; do not interpret a Googlebot request as proof of an AI citation.
Cloudflare AI Crawl Control is available on all plans and supports monitoring and allow-or-block rules for individual crawlers.15 Pay per crawl, though, is still a closed beta. Need more teeth than robots.txt? Confirm who the crawler really is, then sit down with the developer on server or CDN rules.
After the fix: validate it and keep a crawl history
After a change goes live, repeat the log file analysis for the affected paths over matching windows. Confirm the agreed behavior before judging crawl allocation or clicks. There's no magic monthly schedule here. Retention, site changes and whatever question you're trying to answer set the pace for reviews.
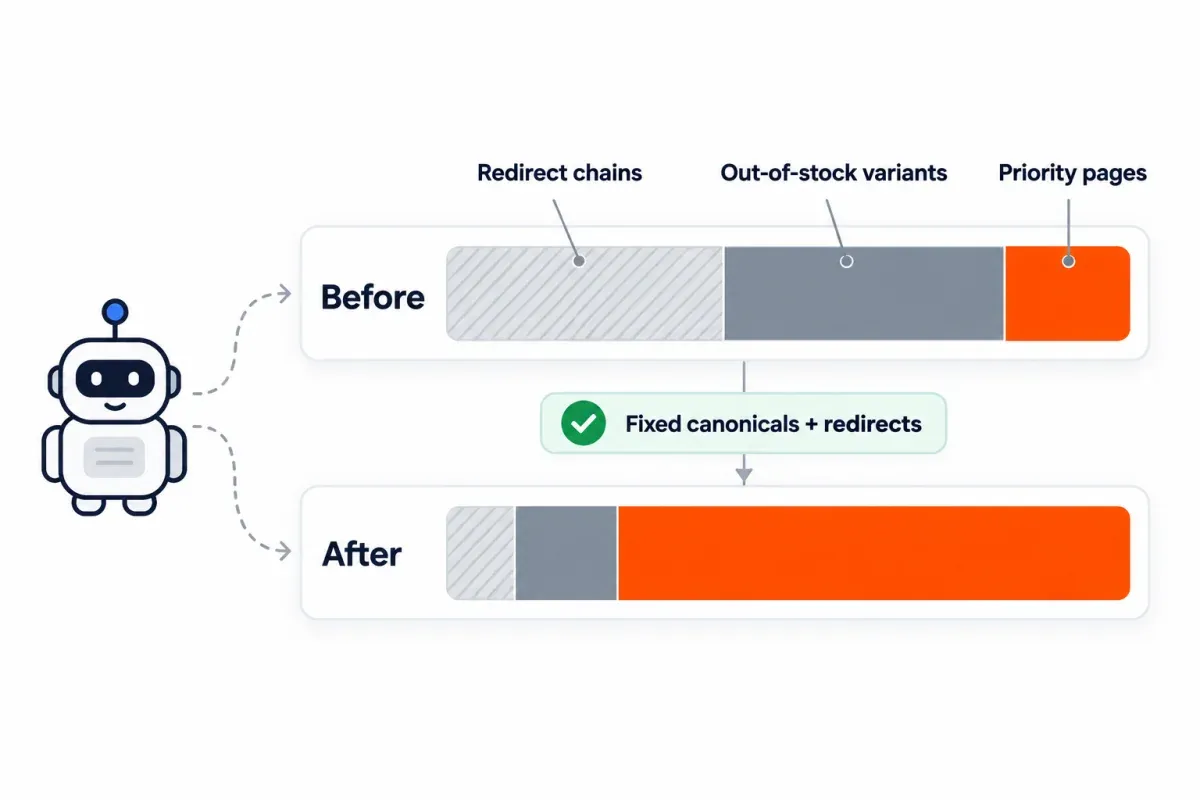
On the next export, run through this:
- Same hostnames, same layer, same time zone as the baseline? Check that first.
- Check whether affected URLs now return the agreed HTTP response.
- Compare error clusters and redirect paths with the pre-change window.
- Check whether repaired internal links appear in the fresh link crawl.
- Look for new verified Googlebot visits to the priority pages.
- For access-rule changes, review the specific crawler's activity and returned codes.
- Recheck Page indexing separately from crawl evidence, then review clicks over time.
Log audit findings worksheet
Use one row per finding or URL pattern, with observations separated from the proposed cause. Leave the diagnosis open when coverage or bot identity is unresolved.
| URL or pattern | Window, hostname and log layer | Bot verification | Response pattern | Page indexing status | Hypothesis and action | Owner and deployment date | Validation evidence |
|---|---|---|---|---|---|---|---|
| [path or pattern] | [dates, host, edge/origin] | [method and result] | [observed codes] | [exact status and check date] | [test, then action] | [owner, date] | [post-change requests and separate indexing check] |
Crawl issue ticket template
The ticket should hand the developer enough evidence to reproduce the issue, plus a response you've both agreed on. Check the deployed change first, then track later crawl and search results.
Title: [section or path] returns [observed response] to [verified crawler]
Log coverage: [date range, time zone, hostname, edge or origin]
Affected URLs: [paths, query strings or attached list]
Bot verification: [IP and verification method]
Observed behavior: [codes, counts and timestamps]
Expected behavior: [agreed response or redirect destination]
Hypothesis to test: [routing, access rule, capacity or other cause]
Priority: [important pages, affected sections and search clicks]
Owner and deployment date: [name, date]
Validation: [post-change log window, response check, indexing follow-up]
For ranking the findings, SEO Heatmap lines up each page's Search Console clicks, grouped by site section. Its monthly and weekly views show which affected sections already earn clicks. Let that steer which developer ticket goes next.
Frequently asked questions
What does log file analysis show for SEO?
You see crawler visits URL by URL (verified bots only), with the time of each request and the HTTP status code it got. Use it to investigate crawl frequency, unnecessary URL inventory and error clusters. Whether Google indexed anything is a question logs can't answer.
How can I analyze log files without buying software?
For a Combined-format export, the command-line summaries in this guide do the job, and a spreadsheet handles a focused comparison of a few URLs. Just confirm the format and check the bot IPs before calling those counts crawler activity. No raw logs at all? Then Crawl Stats is your fallback, though it only covers Google and only works on root-level Search Console properties.
Why are my log totals different from Crawl Stats?
The datasets can differ because of collection coverage, property scope and how Google counts crawl activity. Think about the CDN. Cache hits can be served without the origin ever seeing them, so its logs have nothing to record. Crawl Stats has its own quirks. It reports most requests rather than every one, its URL lists are representative examples, and while robots.txt is unavailable it can count crawls that never happened.
What if my access log has no user-agent field?
Check if it's Common Log Format. That format simply doesn't record user agents or referrers. Apache ships with Common by default, while nginx uses Combined, and so does Debian's default Apache site configuration. Without those fields there's nothing for a user-agent filter to match. Talk to the server owner about logging what the bot-verification workflow needs.
Can a 200 response explain why Google hasn't indexed a page?
No. All a 200 proves is that the fetch succeeded then. Why Google didn't index the page is another question. Start from the exact Page indexing status. Directives come next, then duplicate signals and canonical selection, then the rendered content and soft 404 symptoms. Don't jump to content quality just because the response was clean.
Which logged errors need an urgent server check?
Clusters of 5xx or 429 responses on pages meant to be public go to the top. Google says both slow crawling for a while. If the server errors persist, pages can drop out of the index. Hand the developer the paths and timestamps. Once the change ships, the post-change logs should show the agreed behavior.
How much log history should I keep for an audit?
Enough to compare the affected paths before and after a change, with the same coverage on both sides. Your host's retention window sets the pace: Kinsta keeps logs for up to four days, WP Engine Edge the past 72 hours. Cloudflare Logpush can't fill in the past, either. Set it up well before you need a baseline.
Should I block GPTBot and allow other AI bots?
That comes down to what access you're willing to give and how much load you're seeing. Training is GPTBot and ClaudeBot's job (what they collect may end up in model training). OAI-SearchBot, Claude-SearchBot and PerplexityBot work for AI search instead. User-triggered fetchers are their own case. Robots.txt is a weak lever for them. ChatGPT-User may not be bound by it at all, per OpenAI, and Perplexity-User generally ignores it.
Fixed something your logs surfaced? SEO Heatmap shows whether the affected pages' clicks moved afterward, with 16 months of Search Console history for every page. It's free for one Search Console property.
Sources (15)
SEO Heatmap Knowledge relies on primary sources: Google's documentation, web standards, peer-reviewed research, and vendors' own pages for their pricing and features. Our editorial standards
- Apache Software Foundation. “Log Files.”
- Google Search Central. “Googlebot.”
- Cloudflare. “Logpush is now available on all plans with usage-based pricing.”
- Cloudflare. “Logpush.”
- Cloudflare. “HTTP requests.”
- Google Search Console Help. “Crawl Stats report.”
- Google Search Console Help. “URL Inspection tool.”
- Google Crawling Infrastructure. “Verify requests from Google crawlers and fetchers.”
- Google Crawling Infrastructure. “Optimize your crawl budget.”
- Google Crawling Infrastructure. “How HTTP status codes affect Google's crawlers.”
- Google Search Console Help. “Page indexing report.”
- Lopez-Fonseca et al., arXiv 2026. “Do Generative AI Assistants Respect robots.txt? Tracing Web Access Beyond Visible Answers.”
- Apple. “About Applebot.”
- Google Search Console Help. “Search generative AI control.”
- Cloudflare. “AI Crawl Control.”

