

Summarize this article with AI
Seeing "Discovered - currently not indexed" in Search Console? Look first at the pages you actually want people to find. Sort them away from the URL variants you never wanted, and only then pick a fix. The real question is which of the affected pages are worth your time.
What follows mixes Google's documented guidance with ordinary audit practice to get you that answer. You'll slice up the report, tell crawl capacity apart from crawl demand, and let the evidence pick the fixes. A worksheet and a developer ticket then turn that diagnosis into a fix you can check.
What "Discovered - currently not indexed" means, and the first thing to check
"Discovered - currently not indexed" is a page status in Google Search Console that means: Google found your URL but hasn't crawled it yet.1 Pick an important affected page, open its indexed result in URL Inspection, and ask whether that URL belongs in search at all.
Google's Page indexing help says Google typically expected a crawl to overload the site, so it rescheduled the crawl.1 Hence the blank last crawl date in the report. The URL sits in Google's crawl queue until Googlebot returns. So it's a state worth investigating. Nothing in it points to a particular server error, or a particular content flaw.
Key takeaways
- Read the indexed result in URL Inspection first; save the live test for checking current access.
- Prioritize intended search pages, then group them by template and submitted status.
- Keep server capacity in its own column, apart from crawl demand, links and unwanted URL inventory.
- Repair whatever the audit finds, request crawls only where they'd help, and go back to the very same URLs afterward.
Search, as Google tells it, runs in three stages, crawling first, then indexing, then serving. And step one of crawling is simply finding the URL. It finds URLs on pages it already knows, through links, or in sitemaps you submit. Google does not guarantee that it will crawl, index, or serve a page in search results.2
"Discovered" versus "Crawled - currently not indexed"
| Search Console status | What Google reports | Start your investigation here |
|---|---|---|
| "Discovered - currently not indexed" | Google knows the URL but has not crawled it | Crawl access, internal links, server health, unwanted URLs, and demand |
| "Crawled - currently not indexed" | The page was crawled but not indexed; it may or may not be indexed later | Content usefulness, duplicates, canonical choices, and what Google fetched |
Use what follows as audit starting points; the causes can overlap. If the indexed result reports the second status, use the workflow for pages already crawled. For "Crawled - currently not indexed," Google's help says there is no need to resubmit the URL for crawling.1
Should you fix it or monitor it?
Not every "Discovered - currently not indexed" URL needs your attention.1 Start with business importance, the affected templates, the trend, and the share of intended search pages involved. Do not base the decision on an arbitrary URL count or waiting period.
| What your review shows | Recommended decision | Next check |
|---|---|---|
| Important product, landing, or editorial pages remain uncrawled | Investigate | Inspect those URLs and compare their links, sitemap inclusion, and access |
| A growing share of submitted pages is affected | Investigate the section or template | Compare server health and URL inventory with the report trend |
| Only unwanted filter variants or utility URLs are affected | Review URL controls rather than trying to index them | Decide whether to consolidate, prevent crawling, or use noindex |
| A stable set of lower-priority URLs is affected, with no known access problem | Monitor while reviewing their purpose | Record the same URLs and compare their reported state later |
Just launched a section? Check how it's set up, and don't promise anyone that waiting will clear the status. How often you review it should depend on its business impact and your release schedule.
Segment the report before you fix anything
Open Google Search Console → Indexing → Pages → Why pages aren't indexed, then select "Discovered - currently not indexed." You'll get a trend chart on the details page, and a list of example URLs. The export includes the chart and table data, but the table is capped at 1,000 rows and does not necessarily contain all affected URLs.1
Use the Page indexing report's sitemap filter to compare these groups. A URL counts as submitted here only if its sitemap was submitted through the Sitemaps report or referenced in robots.txt.1
| Filter | Audit question |
|---|---|
| All known pages | Which URL patterns appear across the property? |
| All submitted pages | Are URLs we submitted for search affected? |
| Unsubmitted pages only | Is Google finding unwanted URL variants, or useful pages missing from our submitted set? |
| A specific sitemap | Is one section or template affected? |
Inspect representative pages from each affected pattern. Read the indexed result for Google's recorded indexing state, and use Test live URL separately for current accessibility. A successful live test does not mean the page is in the index.3
Sample 10 to 20 URLs across the main patterns to begin with, and widen it wherever the evidence splits. Check the examples against your own list of intended URLs and a site crawl. The export isn't the full inventory. This worksheet keeps what you saw separate from what you concluded.
AUDIT: "Discovered - currently not indexed"
Property / hostname: [ ]
Report filter and date checked: [ ]
Affected count and trend under that filter: [ ]
Intended search URLs in this section: [ ]
Affected share of intended URLs: [ ]
URL or template sampled: [ ]
Indexed-result status and crawl information: [ ]
Live-test access result: [ ]
Submitted sitemap: [ ]
Crawlable internal link sources: [ ]
Duplicate variants / URL parameters: [ ]
Server evidence: [ ]
Business importance: [ ]
Observed problem: [ ]
Proposed fix and owner: [ ]
Next review: [ ]
Is it a crawl budget problem? Google's own test
Google defines crawl budget as the set of URLs it can and wants to crawl.4 Its crawl-budget guide explicitly includes sites with a large share of URLs reported as "Discovered - currently not indexed." That makes the affected share a useful signal regardless of site size.
The guide also names sites with 1 million or more unique pages changing about weekly, and sites with 10,000 or more unique pages changing daily.4 Those numbers are ballpark figures, by Google's own description. A smaller site isn't automatically in the clear on crawl budget. On a small site, look at the affected share and how Google actually crawls it; size alone tells you little.
Do new pages seem to get crawled the day they go live? Then, per Google, a current sitemap and regular looks at the Page indexing report are enough. If not, size up crawl capacity and crawl demand one at a time before you pick a fix. Low demand can reduce crawling even when the crawl capacity limit has not been reached.4
| Side of crawl budget | What Google describes | Evidence to check | Practical response |
|---|---|---|---|
| Crawl capacity limit | How much crawling the host can support; slow responses, 5xx errors, and 429 responses can lower it | Crawl Stats host status, response breakdowns, response-time trends, and "Hostload exceeded" in URL Inspection | Investigate server availability and capacity |
| Crawl demand | How much Google wants to crawl, influenced by size, update frequency, page quality, relevance, popularity, staleness, and perceived inventory | Duplicate URL patterns, unwanted pages, content usefulness, and linking structure | Consolidate inventory and improve useful pages and access paths |
Google treats each hostname as a separate site for crawl budget, including subdomains.4 Put the hostname in your audit notes, or you may end up comparing the wrong servers and logs.
In Crawl Stats → By purpose, Discovery means the requested URL had never been crawled by Google.5 Refresh is Google recrawling a page it already knows. Add a lot of content or submit a sitemap, and Google says discovery crawls should ideally bump up. Read that split next to the affected pages; it won't prove any one page was fetched.
Fixing what the audit turns up
Let the evidence choose each fix; blanket changes across the whole site miss the point. Weak internal linking, content quality and technical access problems are the usual suspects. Which one is yours? The status keeps quiet on that. Below, each pattern gets paired with a task, plus a check to prove the task worked.
| Pattern you find | Task to consider | Verify the implementation |
|---|---|---|
| Wanted pages lack crawlable internal links | Add relevant links from existing pages | Check source HTML and crawlable link paths to the intended URLs |
| Filter, sort, session, or tracking parameters create unwanted variants | Consolidate duplicates or block unwanted patterns after reviewing their purpose | Check preferred URLs, link targets, and the robots.txt file |
| Important templates show slow responses or errors | Investigate server performance | Compare logs, Crawl Stats host status, and response trends after deployment |
| Similar templates offer little unique content | Improve, merge, or remove pages based on their purpose | Review the revised content and intended canonical inventory |
| Submitted URLs redirect or conflict with the intended search version | Correct the XML sitemap and internal links | Check the final canonical URLs in both |
Restore crawlable internal links
Google follows links to reach pages worth crawling, and it reads them as clues to relevance. Its guidance sets a low bar: one link from another page on your site, at minimum, for each page you care about. Begin with the orphans, URLs that no internal link points to. Give each one a link from a relevant page that's already well linked, placed where a reader would be glad to click it.
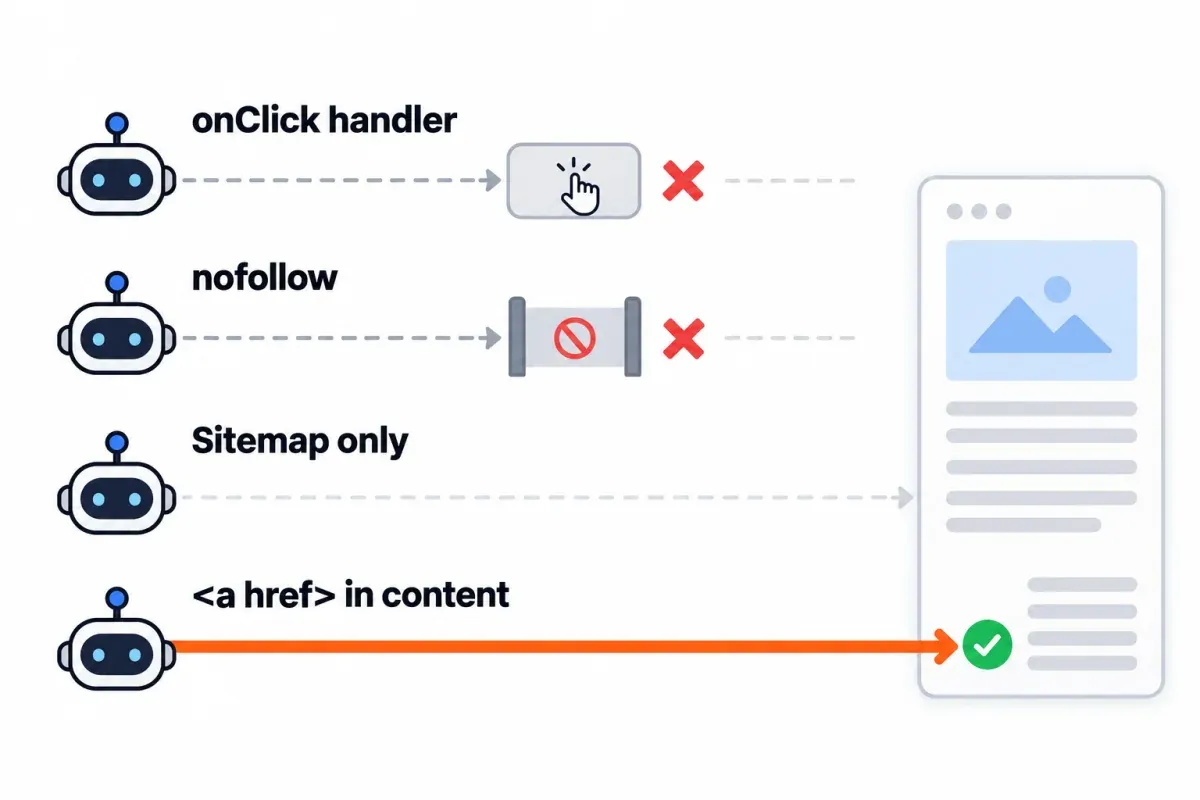
Boring is good here: an HTML <a> element with an href attribute. Script-driven navigation trips Google up. An onClick() handler without a crawlable anchor gives it no reliable destination to extract. Built on a JavaScript framework? Review the navigation in the rendered HTML.
<a href="/guides/example/">Read the related guide</a>
Look hard at nofollow on internal links meant for discovery. Google generally won't follow them, though it can still reach the page through other links. Forget hitting a set click depth. Go through the internal link structure and add category or hub links where they're relevant. A link straight from the home page may make Google see a page as more important and crawl it more often, it says. Rankings are another matter.
Bigger sites can use an HTML sitemap or a hub page as a way down to deep content, for users and crawlers alike. Backlinks help as well. Google reaches new pages through links on pages it already knows. Popularity feeds crawl demand too, which is why URLs that are popular across the web tend to get crawled more often.
Cut unwanted URLs, and keep crawling and indexing straight
Fold duplicate versions together, with a preferred canonical URL or, where it fits, a redirect. Check every variant type: HTTP against HTTPS, www against non-www, trailing slashes, parameters. Should the report flag a canonical issue later on, switch to the duplicate without user-selected canonical workflow.
Robots.txt is the tool for crawlable URL spaces you don't want, like filter or sort combinations nobody needs to find in search. Review parameter patterns before blocking them so intended search pages stay accessible. For permanently removed pages, return 404 or 410; investigate soft 404s rather than leaving empty pages available for repeated crawling.4
| Intended outcome | Control | Limitation |
|---|---|---|
| Prevent crawling of unwanted URL patterns | robots.txt Disallow | A blocked URL can still be indexed without its content if linked from elsewhere |
| Keep an accessible page out of search | noindex | Google must crawl it to see the directive; robots.txt must allow access |
| Remove a page permanently | 404 or 410 | Use this for removed pages, rather than pages you still want indexed |
| Consolidate duplicate content | Canonical or redirect | Check that links and submitted URLs match the preferred version |
If the page needs to be crawled for some reason but shouldn't appear in search, use noindex.1 Google still requests pages with a noindex tag, so this is not an immediate crawl-saving method. Removing URLs from the index can indirectly free some crawl budget in the long run.
Avoid long redirect chains and update internal links to the final destination. Google's crawlers follow up to 10 redirect hops by default, but that limit is no reason to leave chains in place. When you check a redirected page in URL Inspection, inspect the final destination directly: the live test doesn't show which final URL it tested, and the indexed result describes the URL you entered, not the redirect target.3
Fix server capacity problems
When Googlebot gets slow responses or 5xx errors, it reduces its crawl rate to avoid overloading your server.4 Rate-limiting responses such as 429 can reduce capacity too. Enough 500, 503 or 429 responses and Google may slow crawling across the entire hostname.
Go to Google Search Console → Settings → Crawl stats in a root-level property, either a Domain property or a root URL-prefix property.5 Look at total crawl requests, average response time and host status, then the By response breakdown. Check those shifts against your server logs; a response-time spike on its own isn't a diagnosis.
Slow database operations, caching and resource capacity are the first places to dig. Google recommends adding server resources when server capacity prevents crawling, for example when URL Inspection reports Hostload exceeded. Watch the trend rather than a single reading: Google says the capacity limit goes up when response times stay stable or improve, and down when the site slows.4
Don't trust a user agent that says Googlebot; verify the IP first. Reverse DNS should return a hostname ending in googlebot.com, google.com or googleusercontent.com; a forward DNS lookup on that hostname should give back the same IP. Matching Google's published IP ranges works too. The user-agent string by itself proves nothing.
These commands assume combined-format access logs: date in field four, path in field seven, and status in field nine. Run them on a file containing only verified Googlebot requests, named googlebot-verified.log here. Adapt the fields if your log format differs.
# Count responses by status
awk '{print $9}' googlebot-verified.log | sort | uniq -c | sort -rn

# Review requested paths
awk '{print $7}' googlebot-verified.log | sort | uniq -c | sort -rn

# Count requests by day
awk '{print $4}' googlebot-verified.log | cut -d: -f1 | sort | uniq -c
Use the log file analysis workflow for a deeper investigation. If errors dominate the evidence, switch to the Search Console server-error workflow for that problem.
Improve useful content and consolidate duplicates
Google names content quality, relevance, and perceived inventory among crawl-demand factors.4 Every minute spent crawling duplicates and unwanted URLs is a minute not spent exploring the rest of your site.
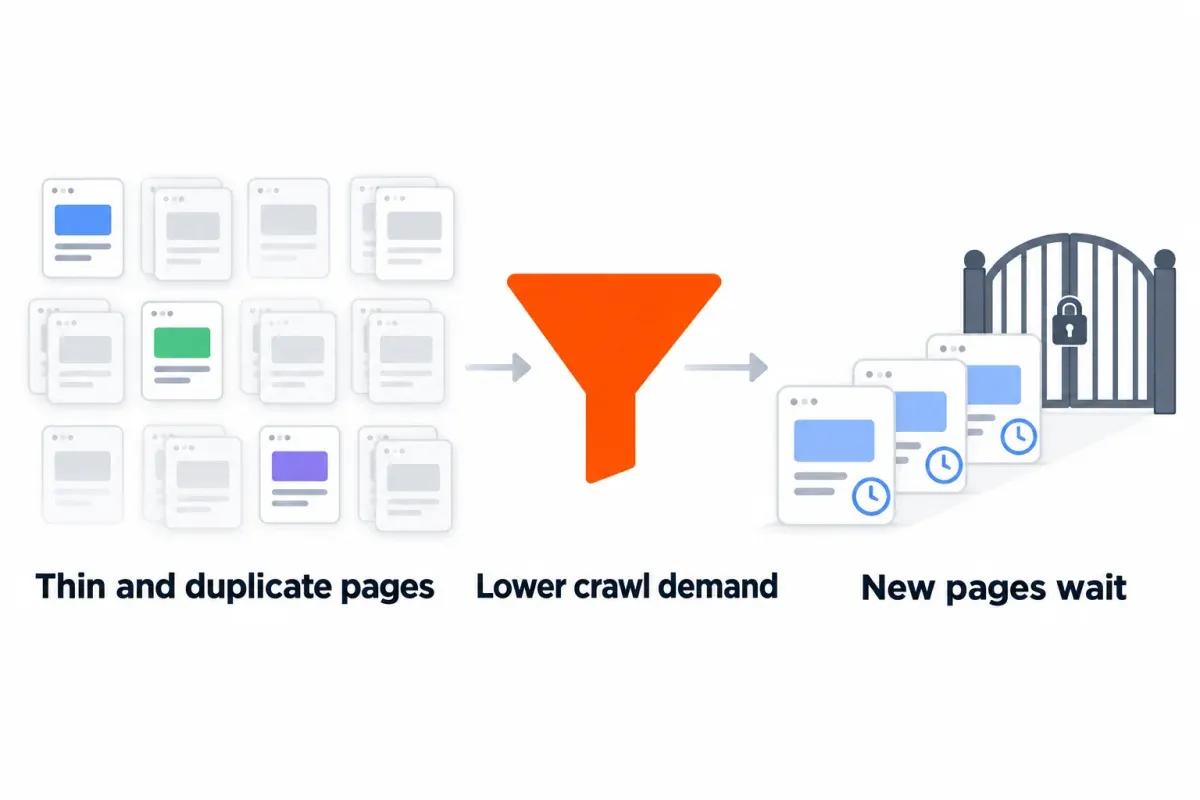
Start the content quality review with affected templates and the purpose they serve for users. Pages worth keeping get improved. Overlapping ones get merged where it makes sense, and the purposeless ones go. Ask these about every template:
- Does it answer something none of its sibling pages do?
- Strip out the shared template text. Is anything unique left that answers the query?
- Would readers be better served by one page instead of a handful of near-twins?
- Weak content: fix it, or admit the page has no job left?
Whatever you decide, the content itself should drive it. High-quality content is worth creating for users, but it is not a guarantee of inclusion in the index.2 The thin content workflow can help organize that review.
Usefulness is the test. How the page got written matters less. Google's scaled content abuse policy covers many pages generated mainly to manipulate rankings rather than help users, whether made through automation, human effort, or both.6 And there's no reason to read a specific crawl penalty into AI-generated text.
Your CSS, JavaScript and XHR files eat into crawl budget as well. If a template drags in a pile of resources, compare what loads with what the rendered page really needs. Assess them alongside URL inventory and server health.
Submit the canonical URLs you want in search
Google describes XML sitemap submission as a hint, not a guarantee that it will download the sitemap or crawl its URLs.7 A stale sitemap helps no one. Keep it current, with the canonical URLs you want found in search. Redirected pages appear in it by their destination, never by the URL that redirects.
Then check the submitted file against this list:
- No URL in it is blocked, inaccessible or noindexed, and each one is meant for search.
- Redirecting URLs and duplicate variants are swapped for their canonical destinations.
- Keep each sitemap under 50,000 URLs (split into multiple sitemaps if needed)7
- Stay within the separate 50MB uncompressed size limit; use a sitemap index for multiple files.8
- Set
<lastmod>to the last significant update, such as main content, structured data, or links, rather than a copyright-date change.7
Google uses <lastmod> when it is consistently and verifiably accurate.7 Two ways in: Search Console → Indexing → Sitemaps, or a sitemap line in robots.txt. For big batches of URLs, Google's recrawl guidance points you the same way.
Request a crawl after checking the page
For an important page you still want indexed, use URL Inspection after addressing the observed problems. Request Indexing asks Google to crawl that individual URL; it does not guarantee inclusion in search.3 You need owner or full-user access in Google Search Console for the action.
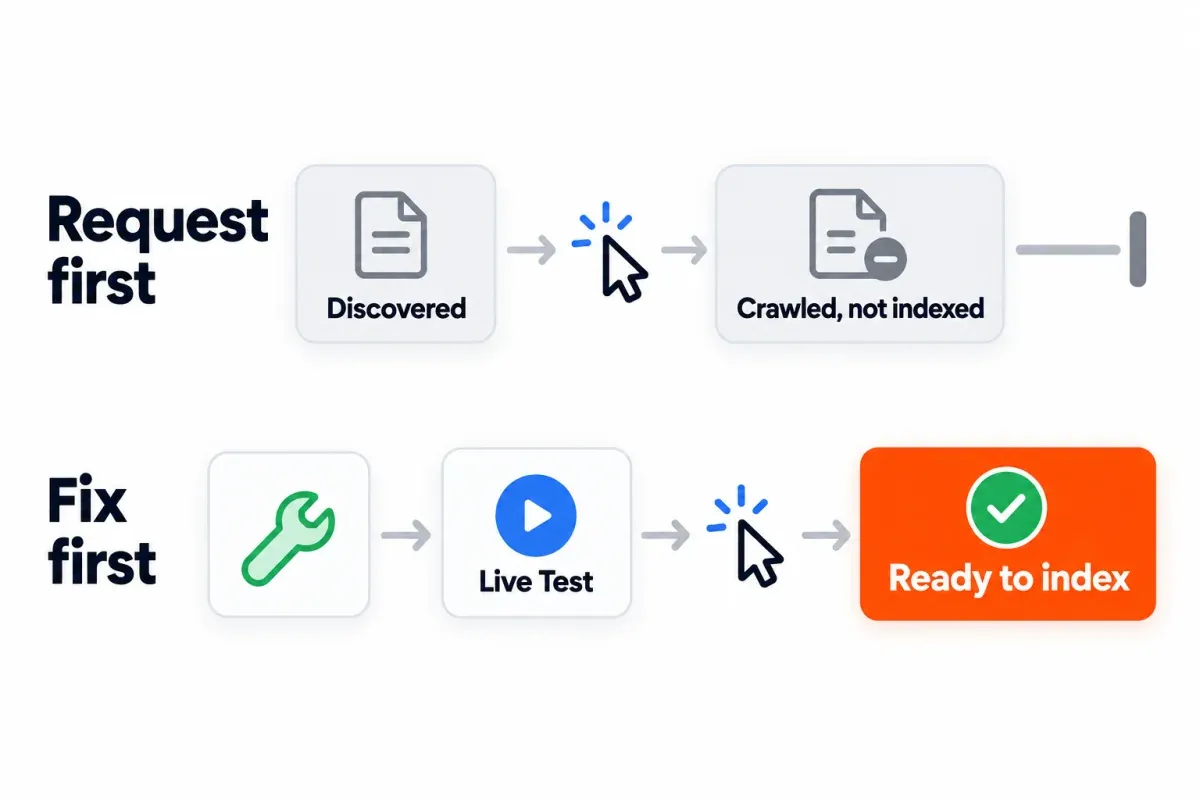
- Open the intended URL in URL Inspection and read its indexed result.
- Select Test live URL to check current accessibility for indexing.
- Resolve the access problems you find and review the page's purpose, duplicates, and content.
- If everything checks out, click Request Indexing3
The live test excludes some indexing issues, including duplicates, quality, and manual actions.3 Passing it cannot guarantee indexing. A fetched page can remain unindexed, which calls for further indexing diagnosis rather than repeated crawl requests.
Google applies a quota to individual URL submissions, plus daily limits on inspections and live tests per property, so prioritize requests for the URLs that matter most.3 Repeating a request for the same URL does not get it crawled faster.
What won't get these pages crawled
Some shortcuts mix up status checks, crawl controls and indexing requests. Skip them. Use each tool for its own job, and leave the URL where it is while you figure out what's going on.
| Proposed shortcut | Google's documented limitation | What to do instead |
|---|---|---|
| Repeated Request Indexing clicks | Repeated requests for the same URL do not speed crawling | Fix the observed issue and monitor the URL |
| noindex to save crawl time immediately | Google must request the page to see noindex | Choose robots.txt for unwanted crawling, or noindex for search exclusion |
| Temporary robots.txt blocks to redirect crawl budget | Google does not shift the available budget unless the site is already hitting its crawl capacity limit | Fix the inventory or capacity issue you observed |
| Adding crawl-delay to robots.txt | Google does not process crawl-delay | Investigate actual server limits and errors |
| Indexing API for ordinary articles or product pages | Google limits it to JobPosting pages or pages with BroadcastEvent embedded in a VideoObject | Submit the canonical inventory through Search Console |
| URL Inspection API as a bulk submission tool | It inspects status; it does not request indexing | Use it for status checks, not submission |
Moving the page to a new URL is a popular one too. Skip it, unless the page needs to move for reasons of its own. Google would have to discover and crawl the new URL from scratch, and whatever link, access, inventory or content problems you found would simply travel with it.
Developer ticket template
Write the diagnosis up as a tightly scoped task, with implementation checks and the search outcome listed apart. Targets and review dates come from your project. Don't dress them up as Google's deadlines.
TICKET: Investigate "Discovered - currently not indexed"
Priority / owner: [ ]
Hostname and affected section: [ ]
Example URLs and complete intended URL inventory: [ ]
Search Console filter and baseline: [ ]

EVIDENCE
Indexed-result status: [ ]
Live-test result: [ ]
Link / duplicate / server evidence: [ ]
Observed cause, or hypothesis to test: [ ]

TASKS
[ ] Apply the agreed fix: [ ]
[ ] Verify access for pages intended for search
[ ] Verify crawlable internal links to intended pages
[ ] Align canonical URLs, link destinations, and XML sitemap
[ ] Confirm robots.txt allows pages that need crawling
[ ] Confirm removed pages return the intended removal status
[ ] Record deployment date and changed URL patterns

ACCEPTANCE AND MONITORING
Implementation checks passed: [ ]
Same sampled pages to inspect again: [ ]
Desired search outcome for each page: [ ]
Report filter and validation scope: [ ]
Business target, owner, and next review date: [ ]
Validate, then keep watching the same URLs
Use Validate fix in the Page indexing report to tell Google an issue has been fixed. It checks all affected instances of the issue unless the report is filtered to a sitemap, which limits validation to URLs in that sitemap.1 Fix the instances within the chosen scope first: validation stops when Google finds a remaining instance.
For a focused review, create and submit a sitemap of your most important pages, then filter the report to it before requesting validation. Google says this subset validation can complete faster.1 Validation reassesses the issue rather than acting as a batch indexing request.
What success looks like
Keep the same filter, URL sample, and intended outcome in your review notes. A lower affected count is useful context, but confirm what happened to those URLs before calling the work complete.
- Verify that the deployed links, URL controls, sitemap entries, or server changes match the ticket.
- For wanted pages, the indexed result in URL Inspection counts; a passing live test alone doesn't.
- A page that shifts to crawled but unindexed has been fetched, so note that, then dig into why it's still out.
- URLs you excluded or removed on purpose need their crawl or removal control checked, not an indexing push.
- Compare Crawl Stats response trends and Discovery versus Refresh alongside URL-level evidence.
Google updates issue counts when it crawls pages with known issues, whether or not you request validation.1 Validation emails report success or failure. These updates do not replace checking the pages you intended to get into search.
| Process | Google's stated timing | What the timing covers |
|---|---|---|
| Crawling after a request | A few days to a few weeks | A crawl, not guaranteed indexing |
| Page indexing validation | Typically up to about two weeks, sometimes much longer | Rechecking the issue, not an indexing deadline |
| Crawl-rate recovery after significant server or rate-limit errors drop | Starts increasing again automatically once the errors drop | The crawl rate for the hostname, not indexing of specific URLs |
Escalate if validation fails or the affected count keeps growing after a completed validation cycle. Recheck the URL patterns that failed validation, then expand your review of logs, access, or content based on the evidence.
To see whether the fixed pages start earning traffic, SEO Heatmap charts clicks per page over time from your Search Console data. URL Inspection remains the place to check each page's recorded indexing state.
Hundreds of URLs to check?
Bigger audits call for the URL Inspection API, fed with your own URL inventory, to pull recorded indexing status in bulk. Its per-site quota is 2,000 queries per day and 600 per minute.9 It does not submit URLs for indexing.
Keep the report's 1,000-example cap in mind when selecting that inventory.1 Start with submitted canonical pages and the affected templates, then compare the same set after changes. Use manual inspection for examples that need closer review.
What indexing means for Google's AI features
Google Search Central says a page must be indexed and eligible for a Search snippet to appear as a supporting link in AI Overviews or AI Mode.2 That rule covers Google's own AI features, not other AI assistants.
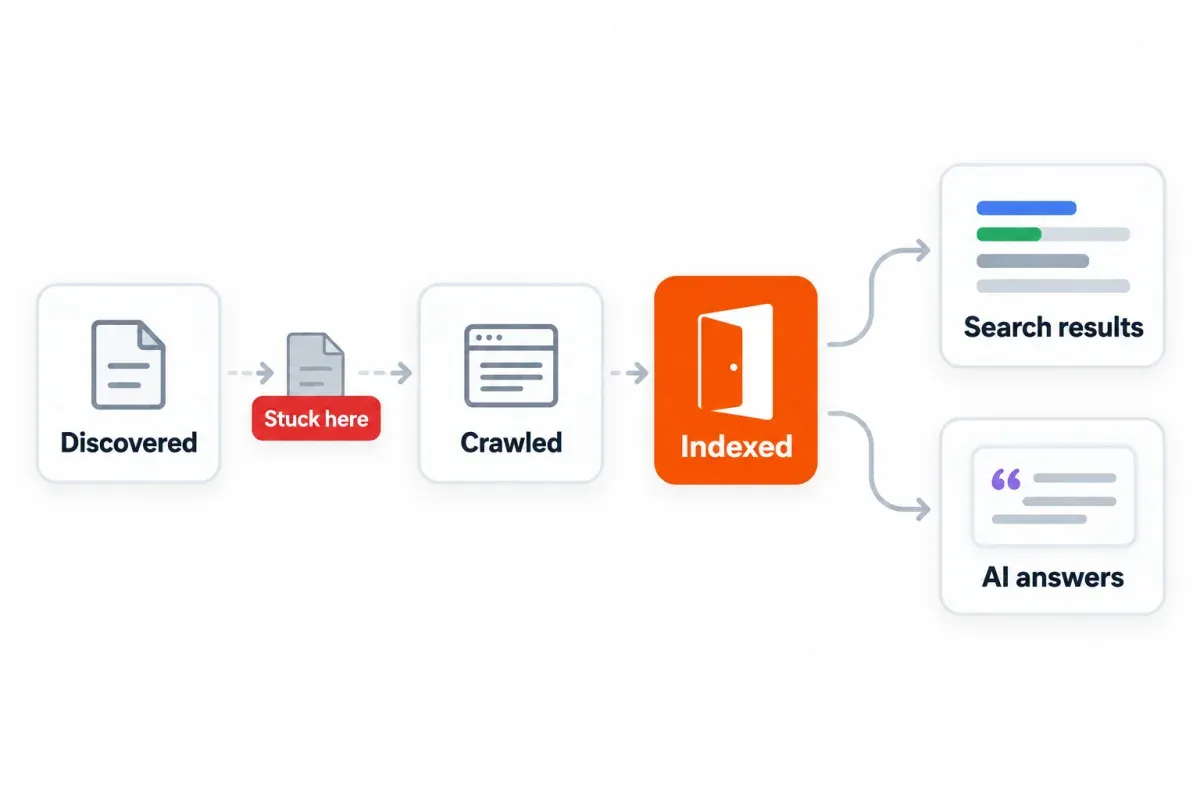
Google lists no extra technical requirements for those supporting links, and no special files or markup are needed.2 So the checks are the ones you'd run for Search anyway: indexing and snippet eligibility. Pass all of that and Google still owes you nothing: crawling and indexing don't guarantee a showing.
Frequently asked questions
What has Google done with a URL labeled "Discovered - currently not indexed"?
It means Googlebot hasn't visited yet, even though Google has the URL on file. The usual reason, per the report: crawling it then looked likely to overload your site, so Google rescheduled. Inspect an important affected page's indexed result before choosing a fix.
What changes if the page becomes "Crawled - currently not indexed"?
The page got fetched at last, but it still didn't make the index. So the crawl happened; the indexing problem isn't solved. Look at usefulness, duplicates, canonical choices and what Google actually fetched. Resubmitting the URL for crawling isn't needed for this status, Google's help says.
When should this status trigger an urgent investigation?
Investigate when important search pages are affected, the affected count grows, or a growing share of submitted pages is involved. Product pages and landing pages deserve attention based on their business role. A stable group of unwanted filter variants calls for a review of URL controls rather than a push to index them.
How long can a page stay discovered before Google crawls it?
Google doesn't give a timeline for this status itself. After a crawl request, Google's own estimate is anywhere from a few days to a few weeks, and indexing isn't promised even then. Base your next step on which pages are affected, where the count is heading and what your diagnosis found. A set waiting period tells you nothing.
Which step comes first when resolving the indexing issue?
Open the indexed result for an important affected URL and ask whether it belongs in search. Segment the Page indexing report by submitted status or a specific sitemap and compare links, URL inventory, and server evidence. Fix the observed problem, use Test live URL for current access, and request a crawl where appropriate.
Can a small website still have a crawl-budget problem?
Yes, site size alone does not rule it out. Google's crawl-budget guide includes sites with a large share of URLs in this status, as well as its rough size estimates. Separate server capacity from crawl demand; low demand can reduce crawling even below the capacity limit.
Why does a successful live test leave my page unindexed?
The URL Inspection live test checks current accessibility for indexing, not inclusion in the index. It excludes some indexing issues, including duplicates, quality, and manual actions. Check the indexed result for recorded status and review the remaining issues instead of repeatedly requesting a crawl.
Does Validate fix submit my affected pages for indexing?
No, Validate fix tells Google an issue has been fixed and starts reassessment. It checks all affected instances unless a sitemap filter limits it to that sitemap's URLs, and it stops when Google finds a remaining instance. Validation typically takes up to about two weeks, sometimes much longer; submit a sitemap for discovery of a large URL set.
Not sure which stuck URLs to audit first? SEO Heatmap shows clicks per page over time from your Search Console data, so you can start with the pages that already earn traffic and see when fixed pages begin to pick it up. It's free for one Search Console property.
Sources (9)
SEO Heatmap Knowledge relies on primary sources: Google's documentation, web standards, peer-reviewed research, and vendors' own pages for their pricing and features. Our editorial standards
- Google Search Console Help. “Page indexing report.”
- Google Search Central. “AI Features and Your Website.”
- Google Search Console Help. “URL Inspection tool.”
- Google Crawling Infrastructure. “Crawl Budget Management.”
- Google Search Console Help. “Crawl Stats report.”
- Google. “Google Search: New updates to address spam and low-quality results.”
- Google Search Central. “Build and Submit a Sitemap.”
- Sitemaps.org. “Sitemaps XML format.”
- Google Search Console. “Usage Limits.”

