

Summarize this article with AI
Pages you actually want in search are sitting in your Page indexing report under "Blocked due to access forbidden (403)." Don't touch the security settings yet. First work out which pages need fixing, and which layer said no.
Below, you'll sort out whether everyone is locked out or only crawlers are, follow the refusal back to its source, and fix it there. Private pages and indexable paywalls come up too, along with how to confirm access without confusing it with being indexed.
"Blocked due to access forbidden (403)": what it means and where to start
A 403 status code means the server understood the request and is refusing to fulfill it.1 Google Search Console reports this specific response as its own status: "Blocked due to access forbidden (403)."2
Should this page be in search at all? That's the first call to make on any 403 Forbidden error. Next, load it while logged out.
If the content also fails in your browser, investigate general access settings. If it loads for you, investigate client-specific blocking before changing file permissions.
| Page you find in the report | Recommended action | First check |
|---|---|---|
| Public page you want indexed | Fix the refusal | Open without signing in, then compare live inspection and crawl evidence |
| Private account page, internal tool, or staging area | Keep the access restriction | Confirm that the page should remain private |
| Paywalled article you want indexed | Allow verified Googlebot access and add paywall markup | Check whether the crawler can reach the paywalled content |
Find the status under Indexing > Pages > "Why pages aren't indexed." Google does not index URLs returning 403.2 It also removes previously indexed URLs returning 4xx responses other than 429.3 So the pages that used to earn search clicks, or that matter to the business, go first.
The report's examples are a starting list, not a complete inventory: Google limits the table to 1,000 rows.2 Copy the affected examples into your worksheet and group them by page type before changing settings.
Key takeaways: Fix access for pages you want indexed, preserve access restrictions on private pages, and identify the responding layer before making changes. Inspection evidence and verified Googlebot logs answer different questions. Compare both when you suspect crawler-specific blocking.
Google Search Console gives 401 and 403 responses their own dedicated statuses ("Blocked due to unauthorized request (401)" and "Blocked due to access forbidden (403)").2 Robots.txt restrictions use "URL blocked by robots.txt," a separate reason from an HTTP refusal. Our guide to "Indexed, though blocked by robots.txt" explains how the two robots.txt statuses differ.
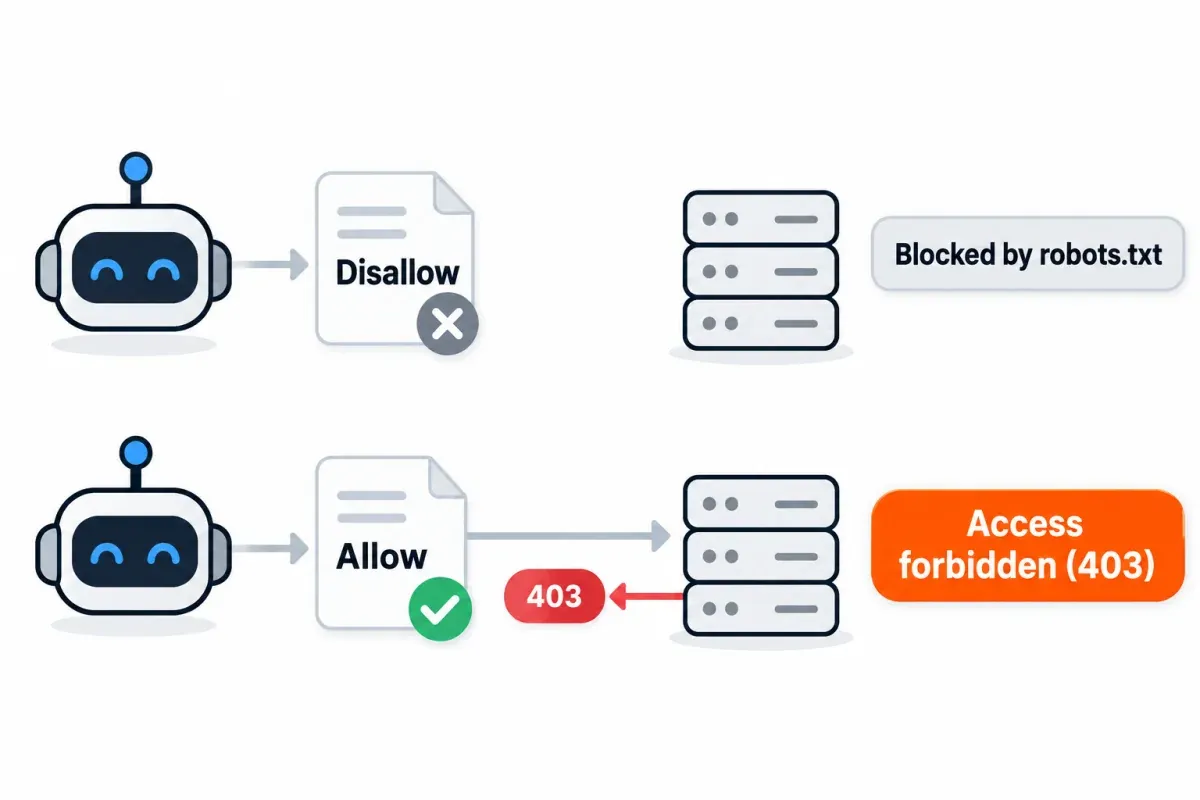
The Google Search Console Page indexing report groups other 4xx responses not covered by a dedicated reason under "URL blocked due to other 4xx issue."2 Google treats 429 as a server error, so don't use the other 4xx troubleshooting guide for a rate-limit response. That one belongs in the server-error guide.
Who gets the 403: every visitor or only Googlebot?
Where you dig depends on what happens in your own browser. Still, a page that loads fine for you proves nothing about Googlebot. Compare the evidence for the same affected page.
| What you observe | Where to start | How to check the repair |
|---|---|---|
| Browser visit without signing in and live test both return 403 | Server access rules, authentication, hosting controls, and security plugins | Repeat both checks and inspect a verified crawl record |
| Browser loads the page, but the live test returns 403 | Request-specific security rules | Match the failed inspection to the blocker’s event or log |
| Browser and live test succeed, but the indexing report still shows 403 | Last crawl evidence and rules specific to Googlebot | Compare the reported crawl with verified Googlebot logs |
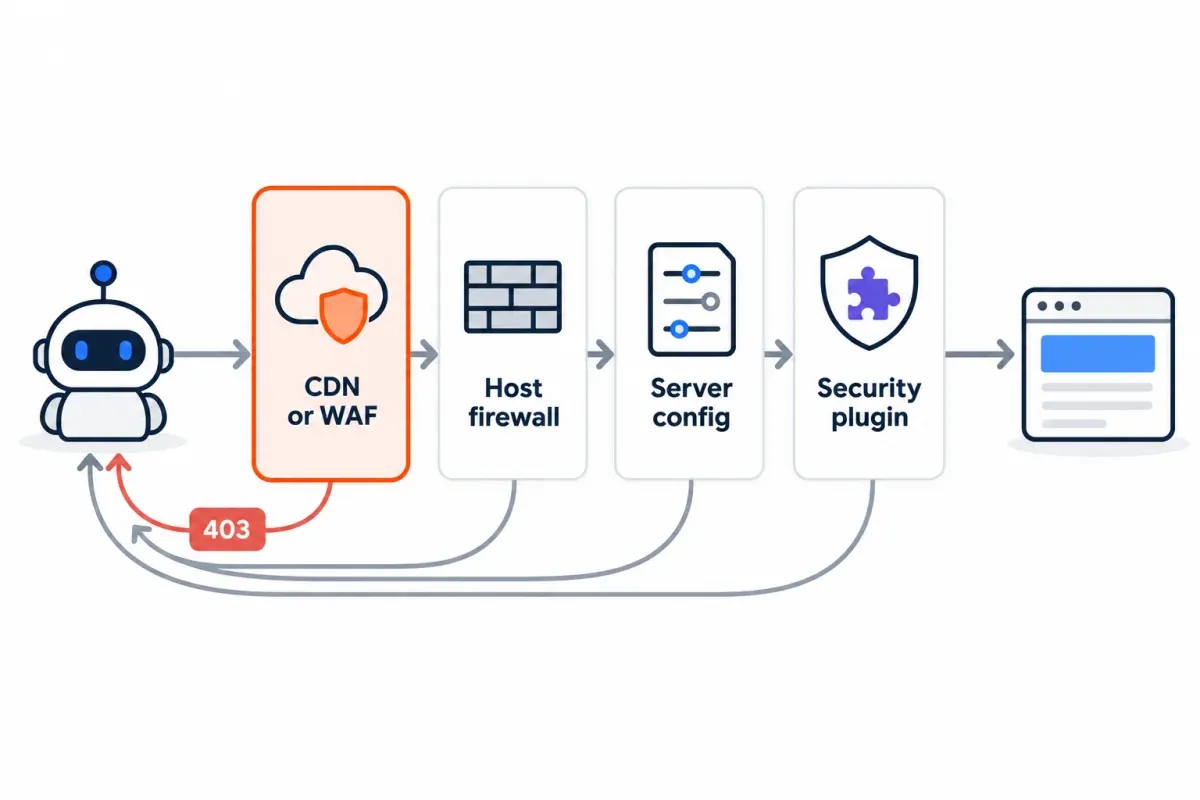
If the page fails for ordinary visitors
Look in .htaccess. If the rules for that page sit in the main server configuration instead, look there. On Apache, watch for Require all denied (nobody gets in, period) and for rewrite rules with an [F] flag on them, since those answer with a 403. In nginx, inspect allow and deny settings; its access module evaluates them in sequence until the first match.4
Got a backup of the .htaccess file or server config? Good. Now change the single directive that blocks the page you want indexed, and nothing else. You might be tempted to delete .htaccess altogether and see what happens. Don't. Maybe the firewall or security rules aren't visible to you. Your hosting provider can check them.
A WordPress site that throws the 403 at everyone? Check the file permissions. WordPress says permissions vary from host to host and that incorrect permissions can take the website offline.5 If something like .htaccess is locked down too far, the server can't read it, and an error is what comes back. A bad permission doesn't prove it caused the 403 Forbidden error, though. Trace the refusal before changing anything.
| WordPress item | What WordPress's file permissions guide says |
|---|---|
| Folders and files | Permissions vary by host; the guide treats 755 for folders and 644 for files as the defaults |
wp-config.php |
It's created with 644 permissions, which WordPress calls a hazard to leave; harden it |
.htaccess |
644 is normally required and recommended |
| Shared hosting that runs PHP through suexec | Directories 755 or 750, files 644 or 640, wp-config.php 440 or 400, and no directory set to 777 |
WordPress warns against 777 outside that setup too: when you see it, ask why it's necessary.5 For a failing directory request, there's one more question for the site operator: which default document is configured, and does that file actually exist? Apache sets this with DirectoryIndex, which defaults to index.html.
When the page loads fine for you
Here the suspects are rules that match on IP address, user agent, country, or ASN, along with hotlink and referrer restrictions. Your host should trace the refusal itself. Loading the page from their own network tells you very little. And no IP goes on an allowlist (or whitelist) until you've confirmed it's really Google's crawler.
By default Googlebot's IPs look US-based, though some of its crawling comes from outside the US. Country-based firewall rules can therefore affect crawler access. Check the country recorded for the refused request rather than assuming your own browser location matches it.
When security plugins are involved, identify which feature issued the refusal. Running Wordfence on WordPress? Its firewall block page says "403 Forbidden" and "A potentially unsafe operation has been detected in your request to this site." Use the matching firewall event to scope an exception for a false positive. Rate limiting in Wordfence is a different beast. It returns 503 by default, not the firewall's 403.
Find the layer that answered, using Search Console and the blocker's logs
Collect evidence before disabling protection or requesting indexing. The worksheet below ties each HTTP status code to the layer that sent it. Old errors go in one place and what you see today goes in another, so the site operator chases the problem that exists now.
Check the indexed result against the live test
Open URL Inspection in Google Search Console and expand Page indexing under the indexed result. The Crawl details there tell you when Google crawled and what got in its way. View crawled page shows the HTTP request and response and the returned HTML, but Google disables that link when there was a problem fetching the page; hover over it to see the reason.6 Then run Test Live URL. No View tested page link? That usually means the live test couldn't reach the page, and that's your live result. The Page Indexing report reflects Google's last crawl, not real time.2
The live test fetches as Google-InspectionTool, not Googlebot.6 All it tells you is whether that tool can get to the page for indexing. A rule matching the Googlebot user agent can treat the crawler differently. Google applies per-property daily limits to live inspections, so choose representative pages when investigating a large group.
Use Crawl Stats and verify log identities
Open Settings > Crawl stats and select Other client error (4XX) to investigate 403 responses. This view groups 403 with other client errors rather than giving it a dedicated row. Its examples include crawl time, response code, and response size. Its totals count requests, not unique URLs.7
Match those examples to the origin server and security-layer logs. Anyone can fake a user-agent string, so a match on its own proves nothing. Verify the IP address using reverse DNS and forward DNS back to the same IP.8 Google's published IP ranges for common crawlers work as a cross-check too.
For reverse DNS, look for a hostname matching crawl-***-***-***-***.googlebot.com or geo-crawl-***-***-***-***.geo.googlebot.com.8 Resolve that hostname back to the original IP before treating the log entry as Googlebot evidence.
Changing the user agent in curl does not verify you as Googlebot. The HTTP status returned to your machine can differ from the crawler's. Use curl to compare specific settings, then confirm crawler access with verified logs.
If the confirmed refusal has no matching server log line, first search the correct log and time range. Then investigate an upstream layer that may have responded before the server logged the request. Use the log-file analysis workflow to organize the evidence.
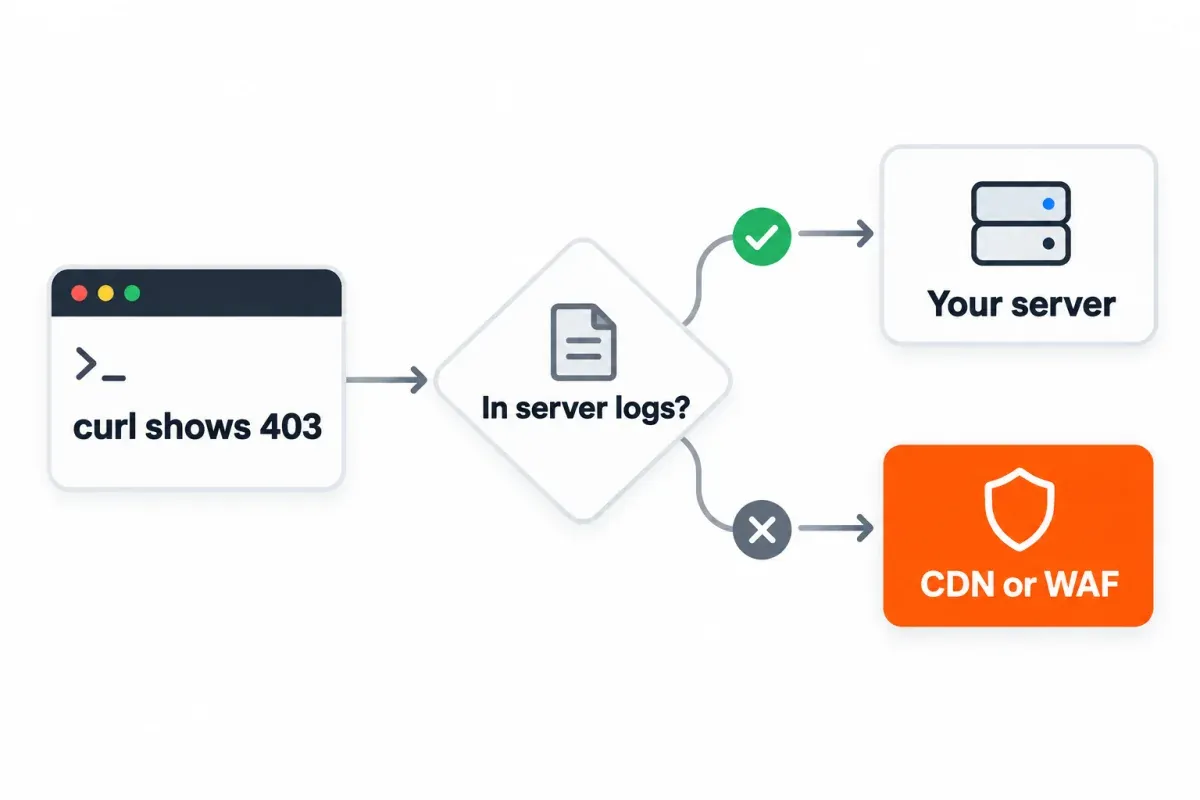
The worksheet below is meant for your issue tracker. Record what you find as you work:
Reported status: Blocked due to access forbidden (403)
Affected page: https://example.com/affected-page/
Should this page appear in search? Public / private / indexable paywall
Browser visit result without signing in:
URL Inspection recorded crawl time and result:
Live inspection time, Page fetch result and HTTP response:
Crawl Stats example time and response code:
Request IP and identity verification method:
Matching origin log / security event:
Responding layer and matched rule:
Next change to test:
Cloudflare: which setting, which fix
Start in Security Events. In the Cloudflare dashboard, that's the Analytics page > Events tab. Match the affected path and request time, then inspect the action and security feature. Cloudflare says its Security Events sampled logs show the action taken and the security feature applied to flagged requests.9
Whatever feature the event names is the one you fix. If it says error 1020, "Access denied," a Cloudflare firewall rule blocked the request. Don't take the Googlebot user agent at face value, either; verify the identity.
| Product or feature | What to check | Matching fix |
|---|---|---|
| Bot Fight Mode | Challenged requests labeled "Bot Fight Mode" in the Service field | Turn it off if testing identifies it as the blocker; custom rules and Page Rules cannot skip it |
| Super Bot Fight Mode (Pro, Business and Enterprise plans) | The action for the "Verified bots" category | Set that category to Allow; use a custom Skip rule for a scoped exception |
| WAF custom rules | The matched rule, action and response code | Narrow the blocking condition or skip the relevant remaining custom rules for verified traffic |
| WAF managed rules | The rule associated with the false positive | Review that rule and use an exception scoped to the affected request |
| Rate limiting rules | The actual response code | A default block is 429; investigate it as a server error. Pro and higher plans can customize a rule's response code |
Bot Fight Mode cannot be tuned through WAF custom rules. To turn it off, open Security Settings, filter by Bot traffic, find Bot Fight Mode, and switch it off.10 If you need exceptions, use Super Bot Fight Mode instead: custom rules run before it, so a Skip rule can exempt matching requests.
In Super Bot Fight Mode, confirm "Verified bots" are allowed rather than assuming they are exempt. The Skip action can bypass remaining custom rules or selected phases: rate limiting rules, Super Bot Fight Mode rules and managed rules.11 Skip only the feature the event points to, and leave the unrelated protections running.
Know that cf.client.bot covers known good bots and crawlers in general, not just Googlebot. Google Search Engine is on Cloudflare's verified list. When designing an exception, review both the identity condition and the pages it covers.
Your settings can stay untouched and the blocking still changes, because managed rules get updated. Note the matched rule identifier and your exception somewhere you'll find them next time.
When to pause Cloudflare (as a test only)
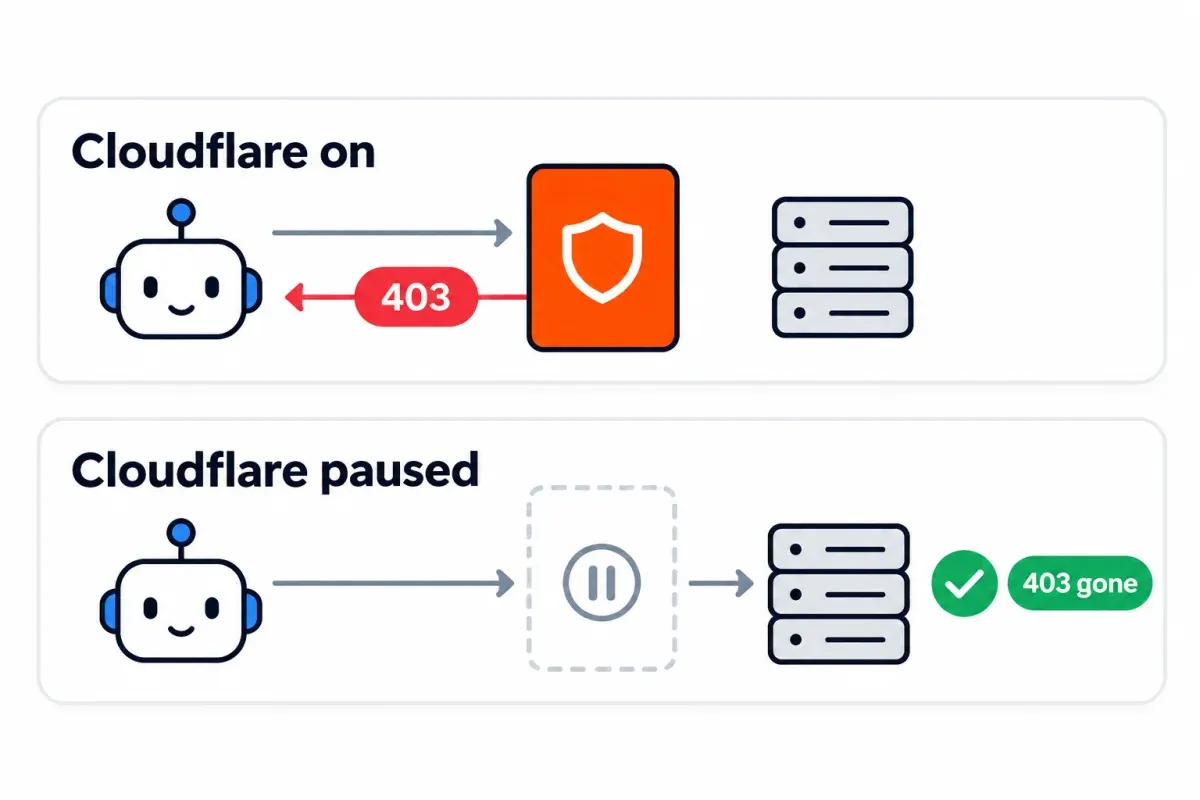
Still no answer from the events? Then agree on a short pause with the site operator. The path is Overview > Advanced Actions > Pause Cloudflare on Site. While paused, traffic goes straight to your origin. The paused domain also loses Cloudflare services such as Rules, WAF and SSL/TLS certificates.12
Compare inspection results with protection active and temporarily paused, then restore the proxy. If the results change, investigate that layer and use its events to identify the specific blocker. Don't leave the zone paused as the permanent fix.
Use this ticket to keep the repair and its acceptance checks together:
Title: Restore public-page crawler access without opening private paths
Affected examples: https://example.com/affected-page/
Evidence: request time, verified identity, status, event and rule identifier
Root cause or rule to investigate:
Proposed change: adjust the matched rule or add a scoped exception
Scope: affected public paths and verified crawler condition
Keep restricted: account, internal and staging paths
Acceptance:
- Visitors who are not signed in can access the public example
- Live URL Inspection can fetch it for indexing
- Verified Googlebot crawl evidence no longer shows the refusal
- Private paths retain their access controls
Rollback: restore the previous configuration if checks fail
Owner and follow-up crawl check:
Login and paywalled pages: leave the 403, or let Googlebot in
Keep login requirements and access controls on content that should remain private. A 401 means the request lacks valid authentication credentials; a 403 means the server refuses it.1 Googlebot does not provide credentials, so content you want indexed needs access for users who are not signed in or a verified crawler.2
For a private account area, staging environment, or internal tool, don't remove authentication to clear a report row. Google says pages returning 4xx responses, except 429, do not waste crawl budget. It also says not to use 401 or 403 to limit crawling, because those responses do not affect crawl rate.3
Paywalled content you want indexed needs a different setup: Googlebot must be able to access the page, including the paywalled sections.13 Mark those sections with isAccessibleForFree: false and hasPart using a cssSelector. Google's paywall markup helps distinguish paywalled content from cloaking; it does not replace crawler access.
Decide whether the paywalled article should appear in search before changing its access rules. If you do not want it indexed, you can leave the restriction. If you do, verify crawler access and the markup together rather than leaving the 403 in place.
Validate the fix while excluding private URLs
After deploying the change, repeat the browser visit without signing in and the live inspection. For crawler-specific blocking, inspect a verified Googlebot log entry too. Confirm private pages still require authentication.
Got an indexable result from the live test? Click Request Indexing in URL Inspection. You cannot request indexing for a page the live test considers non-indexable.6 There's a quota on these, and hammering the button again won't make Google crawl any sooner.
For a batch of repaired pages, submit a sitemap. Keep <lastmod> accurate: it should reflect the last significant page update.14 Google uses it when the dates are consistently verifiable. Don't refresh those timestamps across unchanged pages just to make the sitemap look recent.
Validate fix for "Blocked due to access forbidden (403)" checks instances in the selected report, not just your sample. An unfiltered report covers the issue across the property. A specific sitemap filter narrows that scope.2 Submit a sitemap of important repaired public pages and select it before starting validation when you want to keep private URLs out of the review.
Validation stops when Google finds a remaining instance of the issue. Google can also count an unavailable page, including one requiring authentication, as fixed for that URL.2 A passed validation therefore does not by itself prove that your public content is accessible or indexed.
Google says validation typically takes up to about two weeks, but can take much longer.2 Crawling can take a few days to a few weeks. And asking for a crawl doesn't promise the page a spot in the results. Validation is optional for the count, by the way: it updates whenever Google recrawls pages with known issues.
Changed something in security, server, or plugin settings? Run this checklist so the 403 error stays fixed:
- Test representative public pages with live URL Inspection.
- Review verified Googlebot responses and the relevant security events.
- Check Crawl Stats data and response codes for new access errors.
- Check the Page indexing report after recrawling, separately from live access tests.
- Record the blocking feature, exception scope, and results for private pages.
For prioritizing, SEO Heatmap has each page's clicks over 16 months in the monthly view and 16 weeks in the weekly one. Line up the click histories of the affected public pages; that tells you which access problems come first.
Frequently asked questions
What unblocks a public page that's returning 403 Forbidden?
Find the layer that's turning the request away, then change the rule that's catching your page. How do you find the layer? Compare a logged-out browser visit with the live URL Inspection result. Run both checks again once it's changed. If the rule targeted crawlers, verified Googlebot logs are worth a look too.
The page loads fine for me, so why does Search Console show a 403?
Maybe a rule is waving your browser through and stopping crawlers. Or the report is just showing an older refusal. Compare the recorded crawl with Test Live URL, then trace the matching security event. And because the live test identifies as Google-InspectionTool, a user-agent rule means you need verified Googlebot evidence too.
Is my IP address banned if I get a 403 Forbidden error?
Not necessarily. The server refused the request, and that's all a 403 tells you. An IP ban is just one possibility. Look at which access rule matched before you pick a fix. IP address, user agent, country: rules can match on any of them. Or the page is private and wants a login.
Is robots.txt blocking the same as an HTTP 403?
No. Search Console files robots.txt restrictions under "URL blocked by robots.txt." HTTP 403 refusals have a separate status of their own. Go by the reason Search Console reports; editing robots.txt won't repair a server refusal.
Can Cloudflare block Googlebot even if I allow verified bots?
Check which Cloudflare feature handled the refused request before assuming a verified-bot setting covers it. Super Bot Fight Mode has a "Verified bots" category, but Bot Fight Mode cannot be skipped with custom rules. Other blocking features need their own scoped review using Security Events.
Should paywalled and private pages keep their 403 responses?
Private content can keep its access restriction if it should remain out of search. A paywalled article is different if you want it indexed: Googlebot needs access to all of it, the paywalled parts too. Mark those sections with isAccessibleForFree: false and hasPart using a cssSelector; the markup does not replace access.
Can a 403 remove a page that was already indexed?
Yes, Google removes previously indexed URLs that return 4xx responses, except 429, from the index. Prioritize a refused public page that previously received search clicks. Get access back first. Watch indexing as a separate thing afterward. Requesting a crawl won't guarantee the page comes back.
How long does the error last after I fix it?
The report changes as Google recrawls pages with known issues, rather than immediately after your deployment. Crawling can take a few days to a few weeks. Google says issue validation typically takes up to about two weeks but can take much longer. Confirm current access with live inspection and verified logs while you wait.
After repairing access, track search clicks on the affected pages with SEO Heatmap. Use its page-level history to follow those pages over time; it is free for one Search Console property.
Sources (14)
SEO Heatmap Knowledge relies on primary sources: Google's documentation, web standards, peer-reviewed research, and vendors' own pages for their pricing and features. Our editorial standards
- IETF. “HTTP Semantics.”
- Google Search Console Help. “Page indexing report.”
- Google. “How HTTP status codes affect Google's crawlers.”
- NGINX. “Module ngx_http_access_module.”
- WordPress. “Changing File Permissions.”
- Google Search Console Help. “URL Inspection tool.”
- Google Search Console Help. “Crawl Stats report.”
- Google. “Verify requests from Google crawlers and fetchers.”
- Cloudflare. “Security Events.”
- Cloudflare. “Bot Fight Mode.”
- Cloudflare. “Available skip options.”
- Cloudflare. “Pause Cloudflare.”
- Google Search Central. “Structured data for subscription and paywalled content (CreativeWork).”
- Google Search Central. “Build and submit a sitemap.”

