

Summarize this article with AI
You thought those pages were hidden from Google. Yet there they are in Google Search Console, under "Indexed, though blocked by robots.txt" in the Page indexing report. Could be you blocked something you actually want ranking, by accident. Maybe it's the reverse, and a page you blocked to hide it from search still shows up.
Below you'll track down the cause and choose a fix, which now and then means leaving the warning alone, and confirm the fix worked. If you're on WordPress or Shopify, there's a section on the settings that can add the block.
"Indexed, though blocked by robots.txt" explained, plus your first check
"Indexed, though blocked by robots.txt" means Google indexed the page despite a crawl block.1 It can use information from links without fetching the blocked content.2 So the first step is deciding, for a representative page in URL Inspection, if it belongs in search results at all.
Yes? Then unblock it. If a public page should leave Search, unblock it and apply noindex so Google can read the instruction.3 For deliberately blocked utility pages or facets, check the purpose of the block before making changes.
Google Search Console flags this as its own status, distinct from a normal block.1 Open Indexing → Pages → Improve page experience → "Indexed, though blocked by robots.txt". Plenty of people say error; Google files it as a warning. Since the page is indexed, you won't see it in the Why pages aren't indexed table. Older guides describe the old Index Coverage report, which also filed it under Warning "because we're not sure if you intended to block the page from search results."
Read the warning without confusing it with another status
| Search Console status | What the report means | First check |
|---|---|---|
| "Indexed, though blocked by robots.txt" | Indexed despite a crawl block | Should this page appear in Search? |
| "URL blocked by robots.txt" | Not indexed because of a crawl block (Google says a very small chance of indexing remains) | Was crawling blocked on purpose? |
| "Page indexed without content" | Indexed, but Google could not read its content; this is not robots.txt blocking | Investigate the content-access problem separately |
The practical effect: the URL shows up in Google's index, but usually with a thin or missing snippet, since Google never actually crawled the page content.2 Instead, Google may lean on the URL and on public information, anchor text from links included. The listing can lack a description or display No page information.
Key takeaways:
- A robots.txt crawl block leaves linked pages eligible for Google Search.2
- Noindex and canonical tags on the page only count once Google can fetch it.
- Access can be fixed today. The index updates whenever Google gets to it.
Find out why Google knows the URL
Robots.txt controls crawling, not indexing.2 Google can index disallowed URLs using information from internal or external links. Check navigation, parameterized pages, and old migration paths for those links.
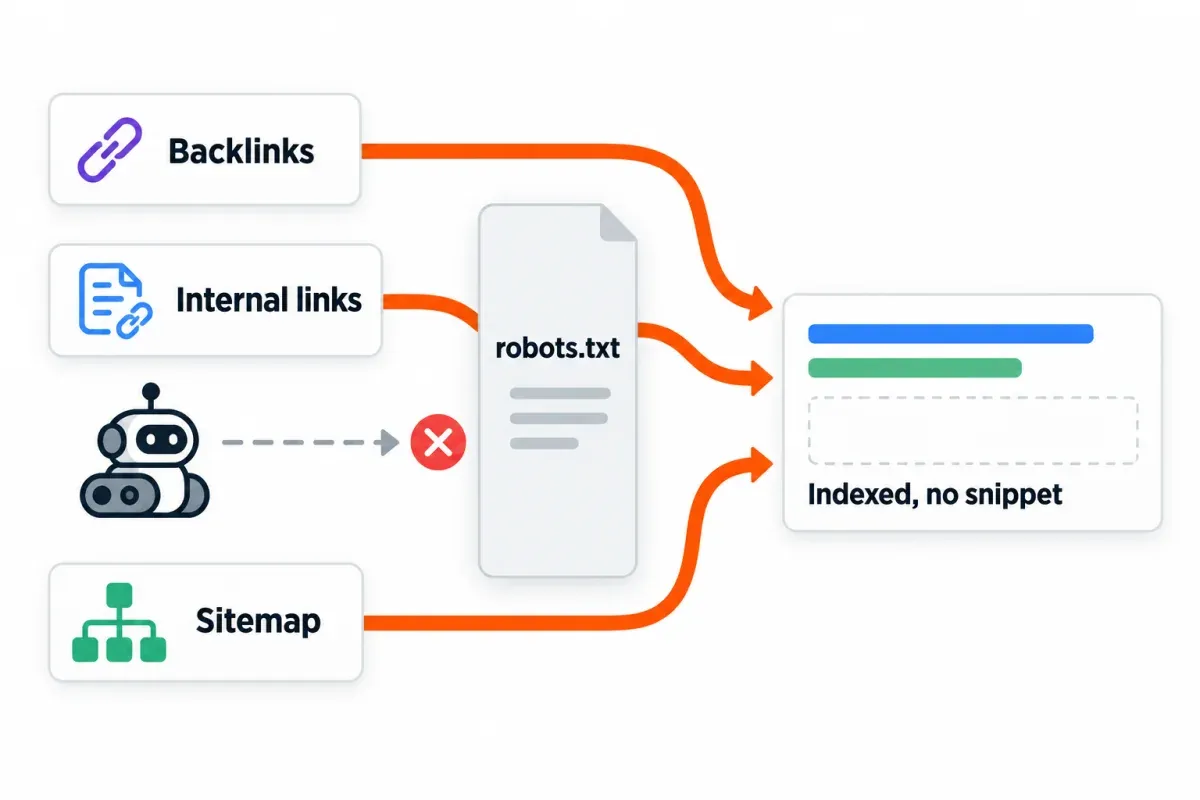
Your starting list is the example URLs, exported from the "Indexed, though blocked by robots.txt" row of the Page indexing report. Group the list by directory, parameter, or old path. The examples table is limited to 1,000 rows and may omit affected pages; treat the export as an audit sample.1
Read the indexed result before running a live test
Inspect a sample URL in Google Search Console's URL Inspection → Page indexing. Use the indexed view for discovery information. Test Live URL fetches the current page but does not check sitemaps or referring pages.4
| Indexed-result field | What it tells you | How to use it |
|---|---|---|
| Crawl allowed? | Whether robots.txt blocked crawling | Compare the reported block with the current robots.txt file |
| Indexing allowed? | Shows Yes when crawling is blocked because Google cannot see a hidden noindex | Do not treat Yes as proof that your tag is absent |
| Discovery: Sitemaps | Submitted or robots.txt-listed sitemaps that point to the page | Check whether the entry belongs in a sitemap |
| Discovery: Referring page | A possible discovery source, which can be an indirect ancestor page | Inspect it for a link; an empty field does not prove there are no referring pages |
Use the Page indexing report's All submitted pages filter to isolate sitemap entries with this warning. Pages count as submitted even if Google found them another way.1 Pick one sitemap if you want a shorter list.
Your XML sitemap should hold the pages you want in Google's search results and drop anything you block or want gone.
A sitemap entry tells you the page was submitted, but Google's own description of this warning names links as the route: it indexes the page "using the information from the page that links to your blocked page."1 So trace the links, not only the sitemap. Copy this worksheet into your audit notes:
Pattern or directory:
Representative URLs:
Should appear in Search / consolidate / stay blocked / be private:
Indexed result: Crawl allowed? / Indexing allowed?
Discovery: sitemap / referring page:
Current robots.txt file: user-agent group and matching directive:
Current page directive or canonical:
Chosen change and owner:
Current crawl access:
Indexing follow-up:
Leave it, unblock it, or noindex it: decide per URL pattern
Choose an action based on the page's role, rather than trying to clear the warning count. Google's Page indexing guidance says blocks are probably intentional.1 For faceted navigation you do not need in Search, Google recommends robots.txt to avoid spending server resources for little benefit.5
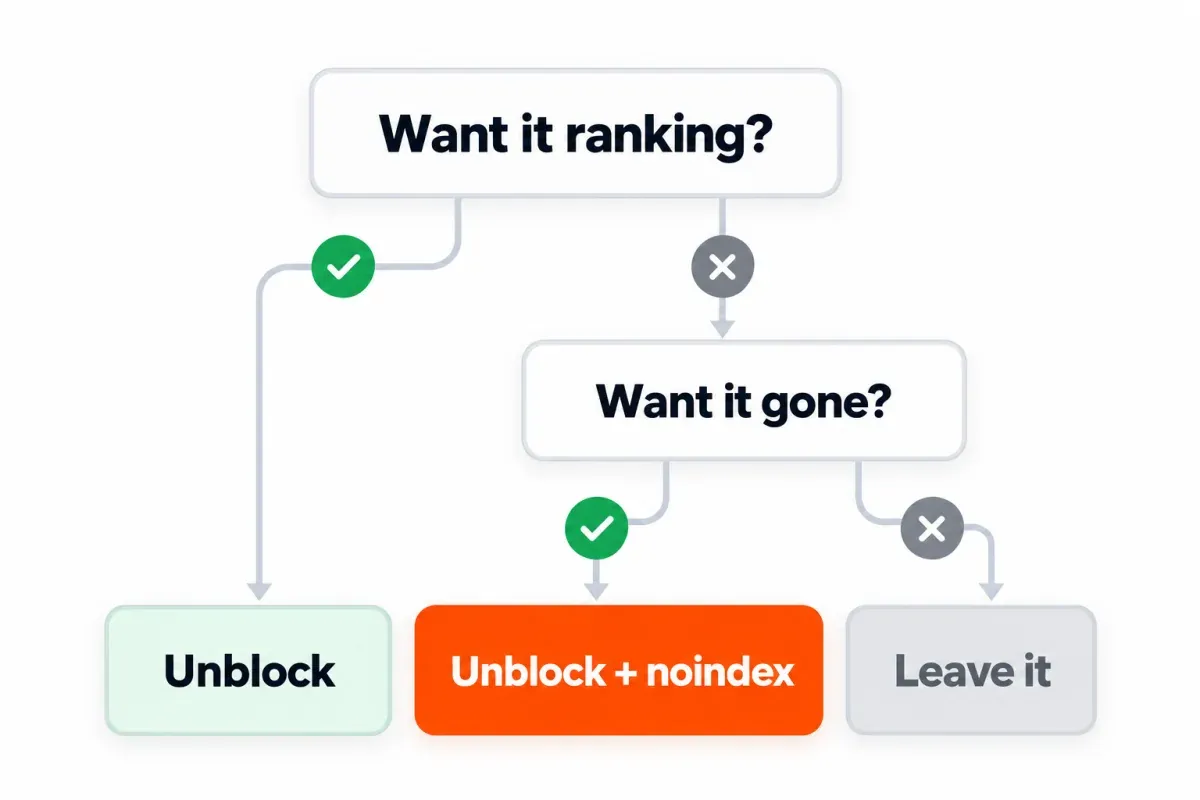
| Page or pattern | Action | What to verify |
|---|---|---|
| Useful content blocked by mistake | Remove or narrow the crawl block | Crawling is allowed and the page has no noindex |
| Public page you want removed from Search | Allow crawling and expose noindex | Google can fetch the page and read the noindex; a later inspection confirms removal |
| Duplicate or parameter page with a canonical version | Allow crawling so Google can read rel="canonical" | Canonical points to the version you want to consolidate signals into |
| Faceted pages not needed in Search | Keep an intentional crawl block | Useful content remains crawlable |
| Shopify cart, checkout, or account paths | Preserve the default crawl controls | The warning concerns a utility path rather than normal content |
| Private content | Password-protect it | Access requires authentication; Search removal is handled separately |
Google advises against robots.txt for canonicalization and against noindex to select a canonical within one site. Google cannot read a blocked page's canonical either. Use rel="canonical" with crawling allowed; follow the alternate page with proper canonical tag workflow for that separate status.
To keep URLs blocked while reducing discovery signals, remove unnecessary internal links and sitemap entries. For faceted pages, nofollow may help, but Google says all anchors to that specific page must carry the attribute for it to be effective.5 Do not expect quick removal through link cleanup. Over the long run, Google sees robots.txt as the more effective tool for facets than canonical or nofollow.
Change the robots.txt rule and let Google in
The file that counts is the one Google receives: /robots.txt as served on that host and protocol. Each host and protocol has its own robots.txt file; subdomains do not inherit from a parent domain.6 Find out what controls that file before you edit anything.
Check the effective user-agent group and path
For Googlebot, a matching User-agent: Googlebot group takes precedence over User-agent: *.7 Editing the wildcard group may leave the block in place. Put the change in the group Googlebot follows.
Matching is case-sensitive and works on prefixes. Disallow: /fish matches /fish.html, /fishheads, and /fish/salmon.html, but not /Fish.asp or /catfish. Google applies the most specific matching rule (the longest path), and when matching rules conflict, it uses the least restrictive one.7
This example keeps the folder blocked. It allows one page:
User-agent: Googlebot
Disallow: /fish/
Allow: /fish/salmon.html$
Google supports * and $ in robots.txt matching.7 Work the fragment into the group you already have. Don't swap your whole robots.txt file for it. Test both sides afterward: the page you unblocked should be crawlable, and its blocked neighbor shouldn't.
Want the page in Search? Unblock it
Remove or loosen the Disallow rule in robots.txt so Googlebot is allowed to crawl the page.1 Check the page for a noindex before asking for indexing. For a duplicate you want to consolidate, inspect its canonical.
To remove a public page, unblock it and expose noindex
Robots.txt tells Google not to fetch the page, so Google never sees the noindex instruction sitting on it.3 Google's Search Central docs say so plainly. Noindex does nothing unless the page is crawlable, meaning no robots.txt block and no other barrier for the crawler.
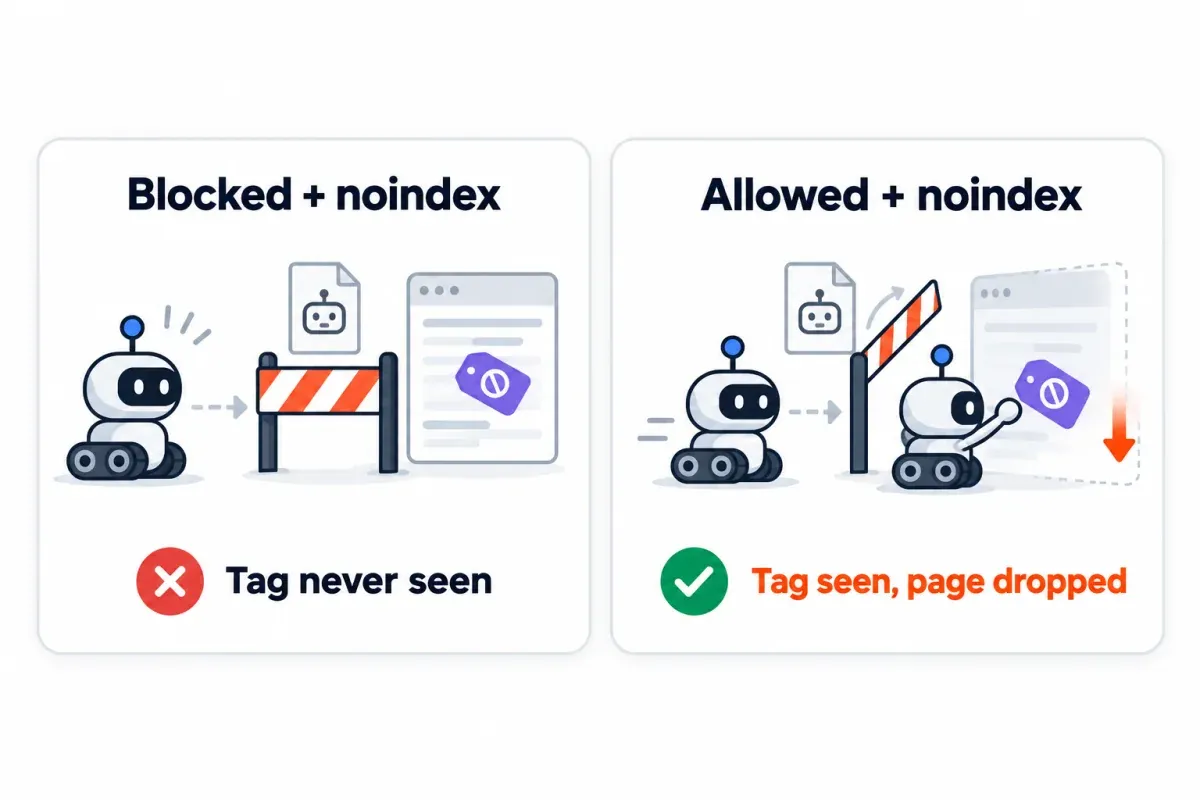
Add (or confirm) the noindex tag on the page itself, either as a meta tag in the <head> or an X-Robots-Tag HTTP header.3 For HTML pages, use something like this:
<head>
  <meta name="robots" content="noindex">
</head>
For non-HTML resources such as PDFs, images, or video, use the response header.3 Set it to noindex:
X-Robots-Tag: noindex
A noindex line inside robots.txt does nothing: Google doesn't support it.3 Put nosnippet behind a block and you hit the same wall, since Google can't read it any more than the noindex. Robots meta tags in the body do get respected, though the head is where they normally go.
Run Test Live URL after unblocking, check Crawl allowed?, and look for the tag in the fetched HTML (or the header in the HTTP response).4 Once Google crawls the page and reads the noindex, it drops the page from Search even if other sites link to it.3
Want it deindexed: follow the unblock-then-noindex sequence above, in that order.1 After that, keep it crawlable. Restore the block and the noindex goes invisible again, and with links pointing at it, the page can still turn up in search results. Use this ticket to keep the change and its acceptance checks together:
Issue: "Indexed, though blocked by robots.txt"
Affected pattern and sample pages:
Goal: appear in Search / remove / consolidate
Effective group and current block:
Proposed robots.txt edit:
Page directive or canonical change:
Sitemap entries to retain or remove:
Acceptance checks:
[ ] Served robots.txt contains the intended change.
[ ] Live test permits crawling for pages to unblock.
[ ] Noindex or canonical is readable where required.
[ ] Neighboring pages retain their intended crawl controls.
Follow-up: inspect indexing and the issue count.
When it has to disappear now: Removals plus noindex
Need it out of search fast? Google Search Console's Removals tool buys time while the permanent fix goes in. A temporary removal hides the page from Google Search for about six months; it does not stop crawling.8 Expect processing to take up to a day, and know that Google can turn a request down.
You can target one page, or a prefix that covers everything you want hidden. Temporary-removal matching covers http/https and www/non-www variants, but not other subdomains.8 Be careful with prefixes, though. One can catch pages you meant to keep visible, so check before you submit.
Permanent removal means one of three things: an accessible page with noindex, content taken down with a 404 or 410, or a password. Google's Removals help is blunt about the one thing not to do: "Do not use robots.txt as a blocking mechanism."8 Private content belongs behind a password. Don't expose it just so Google can read a tag.
Confirm the fix without waiting blindly
Two things update on different schedules: what Google can fetch now and what its index shows. Check the first right after your change; the second follows Google's next crawl. A clean live test doesn't mean the page has left Search yet.
Refresh the file, then test the page
Google generally caches a robots.txt file for up to 24 hours.7 In Settings → robots.txt, use Request a recrawl for the file after changing a block. This does not guarantee immediate crawling of the pages you unblocked.6
The robots.txt report covers the top 20 hosts found on your site, their last fetches, warnings, and errors. It shows the last fetched version and 30 days of version history.6 Use it to confirm Google fetched your new version. The report doesn't test individual pages: for that, Google points you to URL Inspection, which reports whether robots.txt allows crawling of that exact page.
| Check | Keep or restore search visibility | Remove a public page from Search |
|---|---|---|
| Test Live URL | Crawling allowed; no noindex on the page | Crawling allowed; removal tag or header is readable |
| Request indexing | Available only if the live test considers the page indexable; a daily submission limit applies | Not available when the live test considers the page non-indexable |
| Indexed view | Compare subsequent indexing with current eligibility | Confirm that Google has processed removal |
| Report validation | Run after fixing the affected pages | A page marked noindex can count as fixed in the Other validation state |
Validate the warning and monitor the outcome
Open the warning and click Validate fix once every affected page is fixed. Validation checks all instances of the issue, not only those in the examples table (or only the pages in one sitemap, if you filtered the report to it first).1 It stops as soon as Google finds a single remaining instance, so a warning that still includes intentional blocks, such as cart or facet pages, will fail validation. In that case, skip validation: Google updates the count as it recrawls anyway.
Validation typically takes up to about two weeks, but it can take longer.1 Google may take months to revisit a page, depending on its importance on the internet.3 The validation estimate is not a deadline for removal from Search.
Google Search Console updates the issue count whenever Google crawls an affected page, with or without validation.1 If the index lags behind your fix, leave the change in place and keep monitoring.
Where WordPress and Shopify add the block
WordPress: physical file, virtual file, or plugin editor
No robots.txt file in the site root? WordPress then generates a virtual one. A physical file overrides it. If a plugin edit seems to have no effect, open the served /robots.txt and see which version you're getting. The default virtual output includes:
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Yoast's File editor sits in the Yoast SEO menu and doesn't appear if WordPress file editing is disabled.9 Choose the editor for your SEO plugin, then check the served file:
- Yoast SEO: Tools → File editor9
- Rank Math SEO → General Settings → Edit robots.txt, with Advanced Mode enabled. Rank Math's editor requires removing any physical robots.txt file first.10
- All in One SEO → Tools → Robots.txt Editor → Enable Custom Robots.txt.11
In Settings → Reading, Discourage search engines from indexing this site adds a noindex robots meta tag.12 WordPress's default robots.txt has no rule for that setting.13 Seeing Disallow: / on a WordPress site? That came from a physical robots.txt file or a plugin rule; the Reading setting doesn't write it.
Shopify: keep the defaults, check custom rules and per-page hiding
On Shopify, first check whether the URLs under "Indexed, though blocked by robots.txt" fall under Shopify's default blocks. Shopify describes this warning as normal behavior and usually not a cause for concern. Default blocks include /admin, /cart/, /checkout, /checkouts/, /account, /orders, filtered collections at /collections/*+*, and sorted collections at /collections/*sort_by*.14 Preserve those controls unless the affected URLs need different treatment.
For a normal page such as the homepage, Shopify says the warning usually means Google's data about the store is outdated.14 Run a live test in URL Inspection to see what Google can fetch now. Older custom templates can still output /search and /policies/ blocks that are absent from the current default; deleting robots.txt.liquid restores the current defaults.
For pages, blog posts, or products you want hidden, Shopify's seo.hidden metafield set to 1 hides the item from sitemaps, search engines, and online store search.15 Products can also be set to Unlisted, which hides them from internet search and the sitemap.
To customize the file, go to Online Store → theme → Edit code → Add a new template → robots → Create template. Use Liquid to preserve Shopify's ability to update its defaults. Shopify calls this an unsupported customization, and Shopify Support cannot help with edits.14
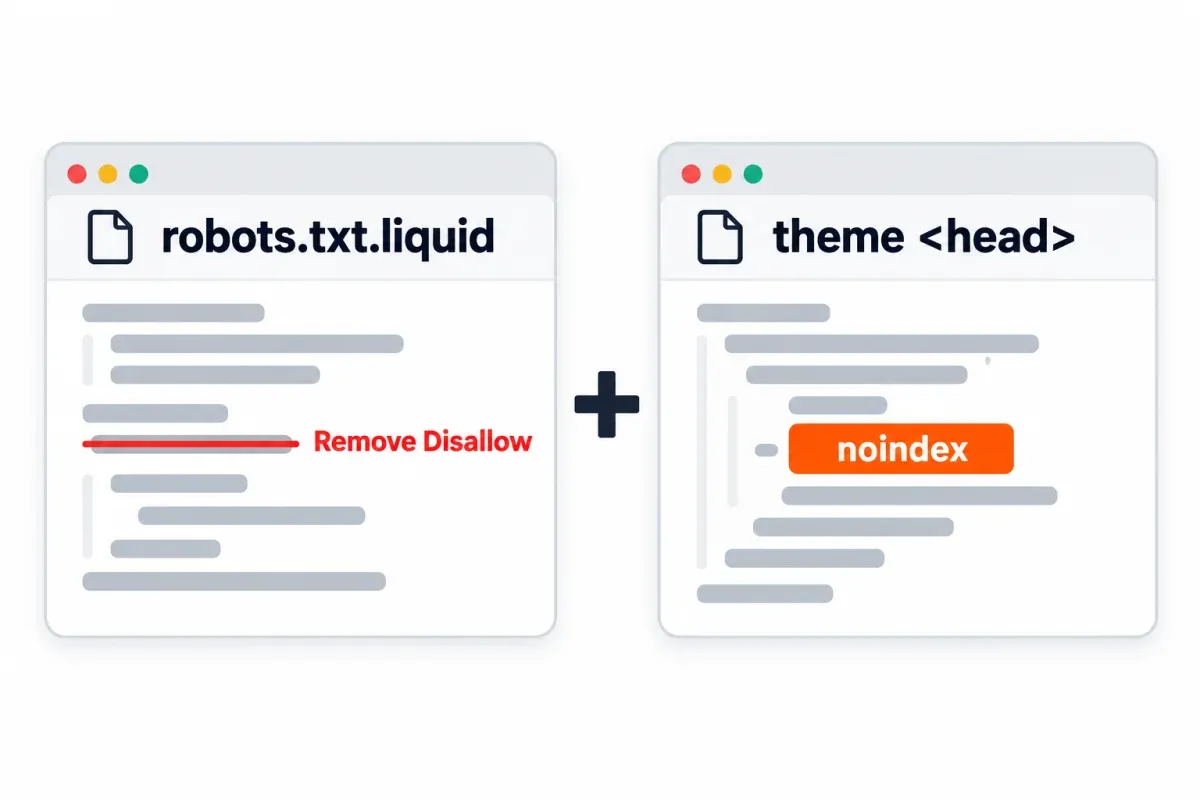
For a page or pattern that seo.hidden doesn't cover, Shopify documents a conditional noindex in the <head> of theme.liquid.15 It's for pages that robots.txt.liquid isn't blocking; swap in your own handle:
{% if handle contains 'page-handle-you-want-to-exclude' %}
<meta name="robots" content="noindex">
{% endif %}
After editing, check the served robots.txt. Check the page's HTML, too.
Prevent repeat warnings without removing useful crawl blocks
New "Indexed, though blocked by robots.txt" examples showing up? Look for a fresh link or sitemap entry pointing into a blocked path before anything else. Your sitemap should list only pages you want in Search. And after a template change or a migration, look at the crawl controls again.
Preserve useful navigation into deliberately blocked paths, such as facets or Shopify utility pages. Prioritize pages whose search visibility conflicts with your plan, rather than removing controls just to reduce the report count. Use this maintenance checklist:
- Group new examples by pattern and prioritize normal content caught in a broad block.
- Compare sitemap entries with crawl controls and page directives.
- Check the live file after a migration or theme change.
- Check the Page indexing report monthly and record why intentional blocks remain.
Thinking of pulling a whole section out of Search? Check its current clicks by page and site section in SEO Heatmap first. You'll have 16 months of monthly history and 16 weeks of weekly. Work out from that history which pages come first, then edit the pattern.
Frequently asked questions
How is "Indexed, though blocked by robots.txt" different from "URL blocked by robots.txt"?
The first is a warning about a page Google indexed despite a crawl block. "URL blocked by robots.txt" is a not-indexed reason in the Page indexing report. And neither one means robots.txt will keep the page out of Search for sure.
Can robots.txt stop Google from indexing a linked page?
Not reliably. A linked page can still be indexed even with a crawl block. It can work from information on the pages that link to it, without ever fetching what's blocked. For a public page you want removed, the answer is crawling plus noindex, so Google can read the tag.
Why does URL Inspection say "Indexing allowed? Yes" when I added noindex?
Because robots.txt blocks crawling, Google never sees your noindex, and the indexed result shows Yes every time. Take the block off and run Test Live URL. It should show Google fetching the page, with the tag in the HTML (or the X-Robots-Tag header in the response).
How do I remove a blocked page from Search while keeping it usable?
Unblock crawling. After that, noindex goes on as a meta tag or an X-Robots-Tag response header. The page has to stay accessible for Google to read that. Search Console's temporary Removals tool handles the urgent cases while the permanent fix takes effect.
Should I unblock cart or faceted pages just to clear the warning?
No. A deliberate block that fits the page's job can stay. Google even recommends robots.txt, in its faceted-navigation guidance, for filtered pages you don't need in Search. Shopify also describes this warning as normal for its expected utility-page blocks, so check the pattern before editing.
Can I safely unblock a private page just so Google reads its noindex?
Not really. Private content should sit behind a password; exposing it to get a tag read is the wrong trade. Noindex handles search visibility; password protection handles access. If the page needs urgent search removal, temporary Removals does not replace that protection.
How long can validation and search removal take after the fix?
Validation typically takes up to about two weeks, but it can take longer. Google may take months to revisit a page, depending on its importance on the internet. Use a live test to check what Google can fetch now, and check the indexed result separately. Don't treat the validation estimate as a removal deadline.
Can Shopify hide a page or product without custom theme code?
Yes. Shopify's seo.hidden metafield, set to 1, hides a page, blog post, or product from sitemaps, search engines, and online store search. Products can also be set to Unlisted to stay out of internet search and the sitemap.
After unblocking content you want found, use SEO Heatmap to track whether those pages start earning clicks. Compare their weekly or monthly history as you monitor the fix. It is free for one Search Console property.
Sources (15)
SEO Heatmap Knowledge relies on primary sources: Google's documentation, web standards, peer-reviewed research, and vendors' own pages for their pricing and features. Our editorial standards
- Google Search Console Help. “Page indexing report.”
- Google Search Central. “Introduction to robots.txt.”
- Google Search Central. “Block Search indexing with noindex.”
- Google Search Console Help. “URL Inspection tool.”
- Google Crawling Infrastructure. “Managing crawling of faceted navigation URLs.”
- Google Search Console Help. “robots.txt report.”
- Google Crawling Infrastructure. “How Google interprets the robots.txt specification.”
- Google Search Console Help. “Removals and SafeSearch reports tool.”
- Yoast. “The robots.txt file in Yoast SEO.”
- Rank Math. “Using Rank Math’s Robots.txt Generator.”
- All in One SEO. “Using the Robots.txt Tool in All in One SEO.”
- WordPress. “Settings Reading screen.”
- WordPress. “do_robots().”
- Shopify. “Editing robots.txt.liquid.”
- Shopify. “Hiding a page from search engines.”

