

Summarize this article with AI
You open the Page indexing report in Google Search Console and find "Blocked due to other 4xx issue" next to a list of example URLs. Some are pages you want in search. Others are admin paths, API routes, and form handlers that were never meant to load for a crawler. The first step is telling those groups apart.
This guide covers which status codes appear in this row, where to find the code Google received, and how to fix common causes. It also explains how to validate repaired pages without expected endpoint errors stopping validation.
"Blocked due to other 4xx issue": fix public pages, leave expected endpoints alone
You see "Blocked due to other 4xx issue" when your server answered with a 4xx code and Google's Page indexing report had no more specific row to put it in. Not every "Blocked due to other 4xx issue" needs fixing.1 The ones worth your time are pages that should be public and showing up in search. Check what each URL is for before you change access rules or request indexing.
Except for 429, which Google handles as a server error, Google doesn't index URLs that return a 4xx code and removes already indexed URLs that start returning one.2 That's why public landing pages come first, and utility endpoints with no business in search results can wait.
Key takeaways:
- Before any of it becomes a to-do list, work out what each page is for.
- Get the real response code (Search Console or verified crawler logs, ideally).
- Fix public-page access, then validate the repaired pages separately from expected endpoint errors.
| What you find | Recommended decision | First check |
|---|---|---|
| Public product, service, or article page | Diagnose and fix | Should visitors reach this content without authentication? |
| Page in a submitted sitemap | Review its purpose | Repair public content; remove a utility endpoint instead |
| URL with prior search clicks or backlinks | Prioritize investigation | Is the page still needed, moved, or deliberately removed? |
| Admin, API, form-processing, or webhook endpoint | Leave expected endpoint behavior alone | Confirm the request is invalid for that endpoint |
| Permanently removed content | Keep the deliberate removal | Google recommends 404 or 410 for permanently removed pages |
My first move with this report is sorting the examples by path. Then I ask what each group is actually for. A tidy path group doesn't prove the error is expected, though, so you still have to confirm each page or resource is meant to be reachable.
Which status codes land here, and which get their own row?
Pay attention to the word "other," because this status leaves out several client errors. 401s, 403s and 404s? Each has its own row in Google Search Console. A 429 isn't here either, since Google's crawlers count it as a server error.
| HTTP status code | How to route the investigation |
|---|---|
| 400, 405, 406, 408, 411, 413, 414, 415, 421, 422 | These codes have no separate Page indexing reason and fit the other-4xx definition |
| 401 | "Blocked due to unauthorized request (401)" |
| 403 | "Blocked due to access forbidden (403)" |
| 404 | "Not found (404)" |
| 410 Gone | Google handles 404 and 410 the same way when crawling and indexing; see which reason your 410 URLs actually show |
| 429 | Google treats it as a server error and temporarily slows crawling |
Maybe the code turned out to be 403. Head to the access-forbidden guide. A 429 goes through the server-error workflow instead. Confirm the status code before applying a fix for another category.
A robots.txt block has a separate reason, "URL blocked by robots.txt."1 Inspect access rules separately from the HTTP status code.
What happened to "Submitted URL blocked due to other 4xx issue"?
The old Index Coverage report had a "Submitted URL blocked due to other 4xx issue" Error reason and an Excluded version. Today's Page indexing report uses a single "Blocked due to other 4xx issue" row. To focus on submitted URLs, select All submitted pages or a specific sitemap.1
With that filter, "submitted" means listed in a sitemap or sitemap index submitted through Google Search Console's Sitemaps report or a robots.txt file.1 Use it to identify pages your website is asking Google to index.
Find the exact code with Search Console's own tools
Annoyingly, the row itself won't tell you the code. URL Inspection and the Crawl Stats report will. Begin with those two. After that, verified logs and curl let you put Google's record next to what your server sends today.
Export examples and sort by purpose
The issue lives under Indexing > Pages > Why pages aren't indexed in Google Search Console; click into it from there. Export the affected URLs as a starting list: the table is limited to 1,000 rows and does not necessarily contain all affected pages.1 The export includes chart and table data.
Read the Source column too. Google says issues with a Website source are generally the ones you can fix.1 Next, split the URLs into path groups like /wp-admin/, /api/, /cart/, and your public content, and spot-check a sample from each.
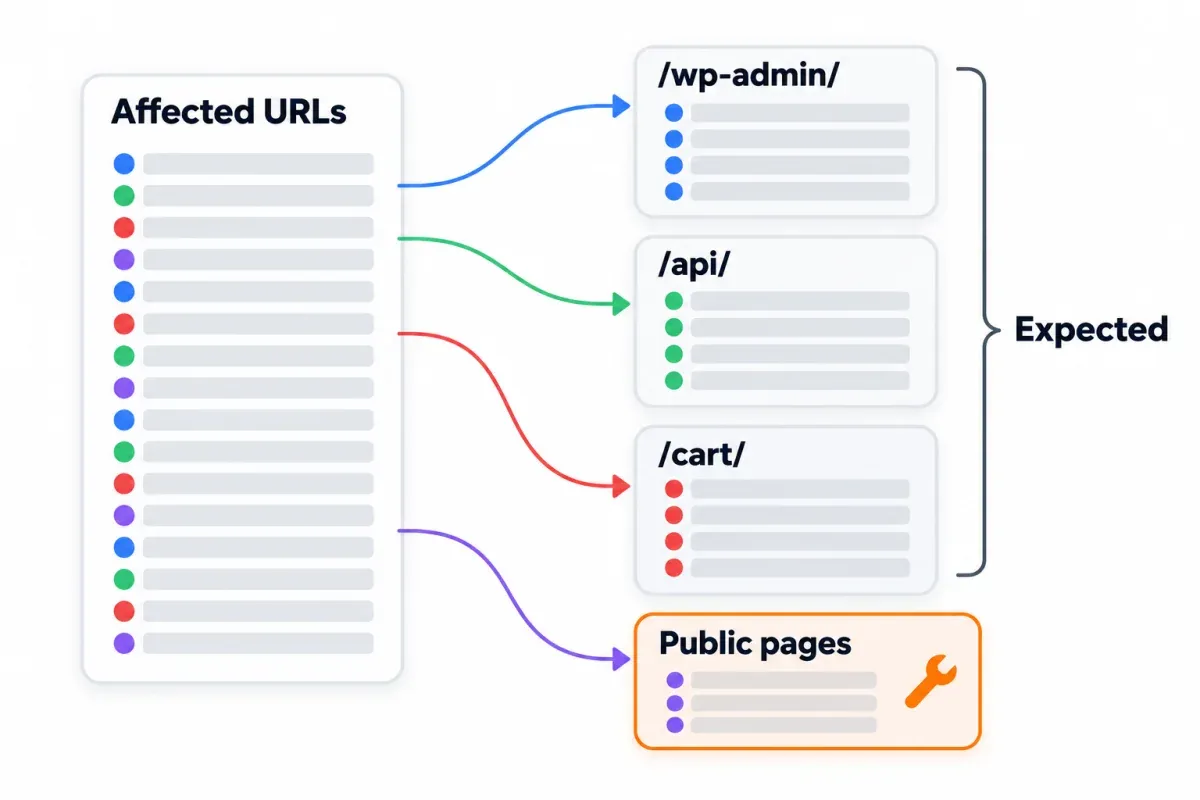
For a broader inventory, review your submitted URLs and server logs alongside the export. Separate known utility endpoints from public pages you plan to repair.
Then check which flagged pages ever earned search clicks. SEO Heatmap shows clicks for every page over the last 16 months, so a page that used to bring traffic stands out from an endpoint that never did.
URL Inspection: indexed result vs. live test
Google Search Console's URL Inspection tool is where to start, with any URL from the affected list. In the indexed result, open View crawled page > More info, when available, to examine the recorded request and response.3 Note the crawl date too.
Then select Test live URL and open View tested page > More info to examine the current response. The live test uses Google-InspectionTool, so success confirms access for that tool.3 It does not prove Googlebot access or indexing.
Google Search Console applies a per-property daily limit to live inspections.3 Save the historical and live findings for representative repaired URLs.
Check Crawl Stats for response codes
In Google Search Console, go to Settings > Crawl stats > By response > Other client error (4XX). Open the group for sample URLs with crawl times and response codes.4 Compare them with your affected URL pattern.
Crawl Stats counts requests, not unique URLs, and calculates percentages from total crawl requests.4 JSON and JavaScript resources appear here too. Its totals therefore differ in scope from the affected-page count.
Use verified logs, then curl for a local check
Filter access logs for candidate Googlebot visits. Adapt this command to your log location and affected path:
grep 'Googlebot' /var/log/nginx/access.log | grep '/affected-page'
A user-agent match does not prove identity. Run reverse DNS on the IP and confirm the hostname ends in googlebot.com, like Google's example crawl-66-249-66-1.googlebot.com, then verify forward DNS resolves back to that IP.5 Alternatively, match the IP against Google's published IP ranges for common crawlers, the group that includes Googlebot.
Use the log file analysis workflow to organize request evidence. Record codes and dates from verified visits.
For a current GET request from your own machine, run:
curl -sS -D - -o /dev/null 'https://example.com/affected-page'
This prints headers and discards the body. Adding a Googlebot user-agent tests that string from your IP, not a verified Google crawl. Bot-verification rules can reject the imitation.
What usually causes it, and the fix for each
You need two things before any fix: the confirmed code, and the URL's job. For public content, ask why an ordinary GET request fails. For an endpoint, review its input requirements before changing how it behaves.
400 Bad Request: check malformed requests and broken internal links
A 400 means the server cannot or will not process a request it considers invalid.6 Start with malformed links or URL encoding: find the source page or template, correct the broken link, and test the target. A site crawler can locate links to the bad path.
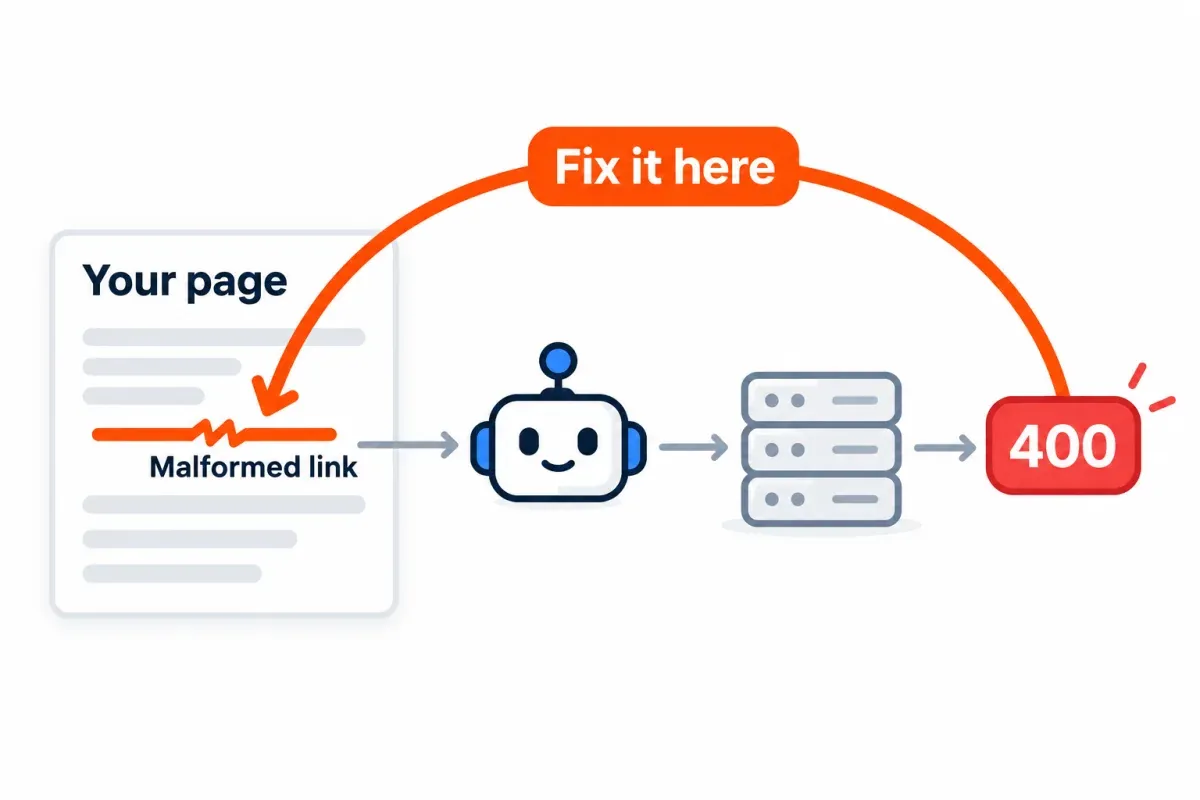
Keep URL length and header size separate. In nginx, a request line exceeding its buffer produces 414, while an oversized request header field produces 400.7 Confirm the code before asking developers to raise limits.
If a page has moved, consider a redirect to its relevant replacement and update the broken links. Not sure which redirect? The 301 versus 302 workflow walks through it. Redirects are for content that moved. They're a bad patch for an endpoint that's restricted on purpose.
408: find where the request timed out
A 408 means the server did not receive a complete request within the time it was prepared to wait.6 Slow page loads are a different problem. Crawl Stats has a separate Page timeout group for timed-out page requests.4
The 408 came from a server, proxy, or load balancer somewhere in the chain; your infrastructure owner or host can say which one. In nginx, inspect client_header_timeout and client_body_timeout, which govern receipt of request headers and body data.7 Check that layer's logs before changing page caching or hosting resources.
Other codes: give developers a specific starting point
Use the confirmed code to narrow the problem. The definitions in the table are from the HTTP standards, and the last column points you at what to check.
| Code | Meaning | Recommended investigation or check |
|---|---|---|
| 405 | Method not supported by the target resource | Read the required Allow response header; find out whether a public page was routed to a form endpoint |
| 406 | No representation acceptable under the request's negotiation headers | Compare those headers with the representations the application offers |
| 411 | Request rejected without a defined Content-Length | Inspect the request and endpoint requirements |
| 413 | Request content exceeds what the server accepts | Check the receiving layer's size limit and expected request body |
| 414 | Target URI exceeds what the server accepts | Inspect long query strings and redirect loops |
| 415 | Content format unsupported for that method and resource | Compare the request format with the endpoint's accepted format |
| 421 | Server cannot or will not provide an authoritative response for the target URI | Check routing to the configured origin |
| 422 | Request syntax is correct, but its instructions cannot be processed | Review application validation and required inputs |
Forwarding the report row on its own leaves a developer guessing, so include the evidence along with the behavior you expect. This ticket template covers both:
Affected page or pattern:
Should this be public content, an endpoint, or removed content?
Page indexing reason and Source:
Recorded request time and response code:
Live URL Inspection status code and indexability:
Verified crawler log evidence:
Suspected emitting layer or rule:
Source internal link or sitemap entry:
Proposed change and owner:
Acceptance check: required content accessible, endpoint rules retained
Deployment date:
Post-change live test and verified crawler evidence:
Firewall and bot rules that answer with a custom 4xx
A firewall rule can put public pages in this report row when it blocks with a custom code that has no Page indexing reason of its own. Take the Cloudflare web application firewall (WAF) custom rules feature: on Pro plans and up, it can send a custom Block response. That feature accepts codes from 400 to 499, with 403 as the default.8
Find the rule that fired and the code it sent before you touch any security settings. If it's the default 403, that's an access-forbidden case, handled separately. A custom 400 or 406, on the other hand, can end up in this other-4xx row.
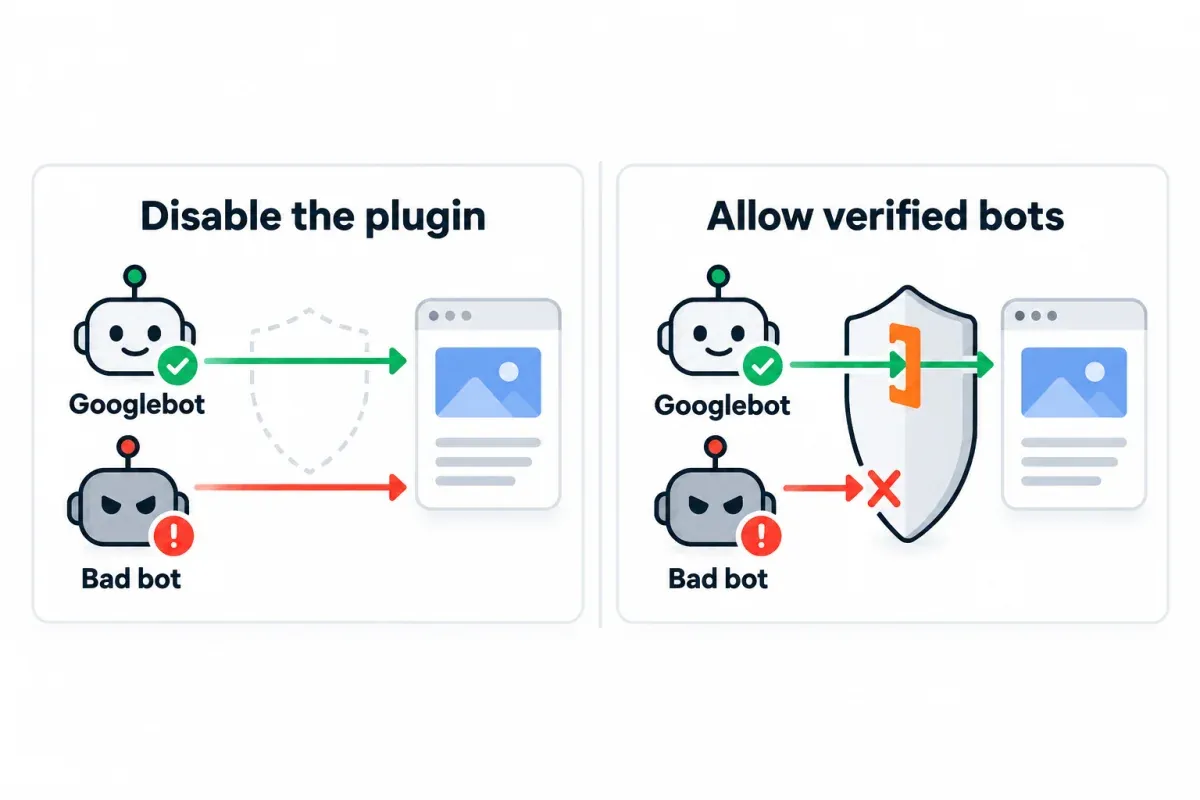
Cloudflare custom rules have a cf.client.bot field for known good bots and crawlers, which lets a rule exempt them. Confirm "Verified Bots" (which includes Googlebot) are allowed.9 Keep the exception narrow: search engine crawlers, public content only. Private endpoints stay locked, and a user-agent string by itself never earns access.
Plugins need the same scrutiny. Wordfence's rate limiting, for one, blocks visitors with a 503 by default, and that's a server-error investigation, not this one. Which layer actually sent the response? Answer that before changing any plugin settings.
What's behind the admin-ajax.php 400 on WordPress
When /wp-admin/admin-ajax.php is the URL in the report, the request's action parameter is the first thing to check. A request with nothing attached can come back 400 for that reason alone: there's no valid, registered action to run. WordPress rejects a missing or non-scalar action, then checks for a registered handler for the visitor's login state.10 Googlebot browses logged out, so that's the handler it hits.
The endpoint reads inputs from both GET and POST, and core registers actions for both methods.10 It also stamps an X-Robots-Tag: noindex header on whatever it returns.
So a 400 on a bare request? Expected. Leave it. It's a different story if something on the frontend is genuinely broken, in which case you'd dig into the inputs it sends and the handler behind it.
WordPress's default virtual robots.txt file includes these rules for a standard admin path:
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
The Allow rule tells Googlebot it's permitted to crawl admin-ajax.php.11 It exists because plugins can use this endpoint on the frontend, where crawling supports rendering. If someone uploaded a physical robots.txt, though, the virtual one is gone, and what your site actually serves is what Google reads.
And no, Disallow: /wp-admin/admin-ajax.php won't override the matching Allow for Google while that Allow is still there. Specificity decides it for Google. If both paths are equally long, the less restrictive one gets the nod. The Allow therefore wins in that pair.
Removing the Allow to block the endpoint can interfere with the frontend resources that motivated it. A robots.txt block also has its own report reason; it does not make the URL disappear from reporting.1 Review the robots.txt blocking guide before changing rules to suppress a report entry.
How to validate the fix when some 4xx errors are expected
There's no point validating before the live test shows the repaired pages loading. And a passed validation doesn't mean the page is indexed, so keep two separate records: one for validation, one for indexing.
Then verify it like this:
- Run Test live URL on representative repaired pages, then check View tested page > More info for the response.
- Got verified Googlebot logs or newer Crawl Stats examples? Compare the response with those.
- Build an XML sitemap of the repaired public pages you want in search, then submit it.
- Filter the Page indexing report to that specific sitemap, then select the issue and click Validate fix.1
- Record validation findings and inspect the pages' indexing status separately.
In Google Search Console's Page indexing report, Validate fix checks every instance of the issue unless you filter the report to a sitemap. With that filter selected, validation applies only to URLs in that sitemap when you start the check.1 Google says validation stops when it finds a remaining instance, so expected endpoint errors can stop a broader validation.
A validation pass is not proof of indexing. Google can consider the issue fixed for a page that is removed, marked noindex, or unavailable because it requires authentication.1 For repaired public content, confirm that the live test considers it indexable rather than relying on the validation label alone.
For a priority page, run Test live URL to confirm Google-InspectionTool can reach it and the page is indexable. Then click "Request Indexing."3 There's a daily quota on individual requests, and asking twice for the same page won't get it crawled any faster.
Got a bigger batch? Use a sitemap. Keep <lastmod> accurate to the last significant page update; don't refresh it for a server-only fix.12
Google says validation typically takes up to about two weeks, though it can take much longer.1 A recrawl might happen in a few days or take a few weeks. Even then, asking for one doesn't guarantee the page gets indexed. You don't strictly need validation, either: Google Search Console refreshes the issue counts whenever it recrawls pages with known issues.
If the page moves to "Crawled - currently not indexed", investigate that reason next. Confirm indexing separately before calling the recovery complete.
Track the repairs and prevent repeat errors
Track repairs separately from expected endpoint errors so a later audit doesn't flag those expected errors for repair again. Replace the bracketed cells with your observations; these rows are work categories, not measured outcomes.
| Page or pattern | Code | Decision or cause | Change | Date | Live test | Verified crawl code | Validation / indexing |
|---|---|---|---|---|---|---|---|
| /public-page | 400 | Malformed internal link | Correct source link | [date] | [result] | [code/time] | [status] |
| /form-handler | 405 | Method requirement | Leave endpoint behavior; remove unnecessary content link | [date] | [result] | [code/time] | [not targeted] |
| /another-page | 408 | Incomplete request | Review responding proxy or server | [date] | [result] | [code/time] | [status] |
| /public-section/ | [custom 4xx] | WAF rule | Scope verified-crawler exception | [date] | [result] | [code/time] | [status] |
| /wp-admin/admin-ajax.php | 400 | No valid action | Leave expected response | [not applicable] | [result] | [code/time] | [not targeted] |
After changes to server configuration, a security plugin, or an .htaccess file, test representative public URLs with Google Search Console. Monitor subsequent Crawl Stats response codes and document bot-access rules. Going forward, check indexing errors once a month and again after any relevant deployment.
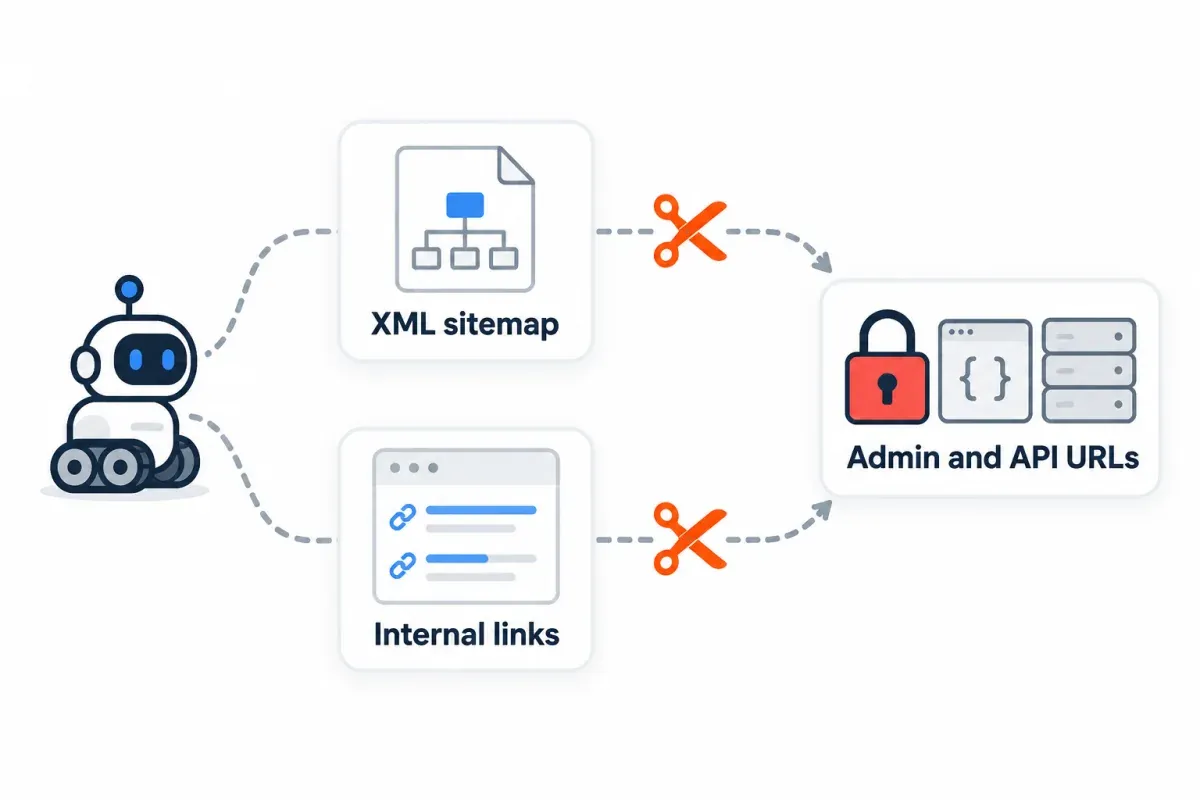
Don't submit URLs you don't want indexed in your sitemap.12 The same goes for needless links to utility endpoints, though public pages still need their rendering resources.
Google says pages serving 4xx responses, except 429, do not waste crawl budget.13 And noindex, by Google's account, won't keep it from requesting a page. So treat link and sitemap cleanup as housekeeping. It's no reason to swap deliberate endpoint handling for a noindex tag.
Frequently asked questions
What does "Blocked due to other 4xx issue" mean?
It means your server sent back some 4xx code (say a 400 or a 405) that doesn't fit any of Google's more specific Page indexing reasons. Google Search Console gives 401, 403 and 404 rows of their own. And 429? Google counts that as a server error.
How do I fix a URL listed under "Blocked due to other 4xx issue"?
Should the URL even be public? Answer that first. If the answer's yes, the exact code is in URL Inspection, Crawl Stats or your verified logs. Fix whatever's causing it next, a malformed link, say, or a custom rule meant to block bots. Retest access and validate the repaired public pages using a sitemap filter; leave expected endpoint behavior alone.
Does a 404 mean my URL was blocked from Google?
It doesn't. A 404 is filed under its own reason, "Not found (404)," and never ends up in the other-4xx row. 403s also get their own row, labeled "Blocked due to access forbidden (403)." So check which code you're dealing with, and the fix follows from that.
Can this status cost a page its organic traffic?
It can, when the URL is public content you'd like to rank. Google won't index a URL that returns one of these 4xx codes, and it drops already indexed pages once they start returning one. Pages that used to get search clicks or have backlinks come first. Utility endpoints that don't need to rank can wait.
Why can a live test pass while this 4xx status remains?
The indexed result describes a recorded crawl, while the live test checks current access with Google-InspectionTool. A successful live test does not prove that Googlebot receives the same response or that the page is indexed. Compare the stored result with the live response and verified crawler evidence.
Why does admin-ajax.php return 400 even when GET is allowed?
A missing or invalid action can trigger the 400, and so can an action with no handler registered for that visitor. Switching methods won't fix it on its own, since the endpoint reads inputs from GET and POST alike. Leave the expected response to a bare request alone; investigate a failing frontend feature's actual inputs separately.
Why does Validate fix fail after I repair the public pages?
A remaining instance can stop validation, including an expected endpoint error in a broader check. Submit a sitemap of the repaired public pages and filter the Page indexing report to it before validating. Validation then covers only its items when you start the check.
How long does Google take to validate these repairs?
Google says validation typically takes up to about two weeks, but it can take much longer. Recrawling can take a few days to a few weeks. A validation pass or crawl request does not guarantee indexing, so check the page's indexing status separately.
After restoring access to a public page, check whether its search clicks return. Open SEO Heatmap to follow that page's click history as you monitor recovery. It's free for one Search Console property.
Sources (13)
SEO Heatmap Knowledge relies on primary sources: Google's documentation, web standards, peer-reviewed research, and vendors' own pages for their pricing and features. Our editorial standards
- Google Search Console Help. “Page indexing report.”
- Google Crawling Infrastructure. “How HTTP status codes affect Google's crawlers.”
- Google Search Console Help. “URL Inspection tool.”
- Google Search Console Help. “Crawl Stats report.”
- Google Crawling Infrastructure. “Verify requests from Google crawlers and fetchers.”
- IETF. “RFC 9110: HTTP Semantics.”
- nginx. “Module ngx_http_core_module.”
- Cloudflare. “Create a custom rule in the dashboard.”
- Cloudflare. “Allow traffic from search engine bots.”
- WordPress Core. “admin-ajax.php in trunk/src/wp-admin.”
- WordPress Core. “Allow admin-ajax crawling.”
- Google Search Central. “Build and submit a sitemap.”
- Google Crawling Infrastructure. “Myths and facts about crawling.”

