

Summarize this article with AI
Search Console flags a "Server error (5xx)," yet when you open the page yourself, it might load just fine. So which request failed, and is it still failing? Those are the two things to pin down.
Crawl Stats is where that request shows up, and from there you follow it through your logs. Then we go layer by layer through the server stack, add a maintenance checklist, and show how to confirm the repair without guessing at a recovery date.
What "Server error (5xx)" means, and the first things to check
"Server error (5xx)" means your server returned a 500-level error when Google requested the page.1 Start with the host status verdict in Crawl Stats, then test an affected page and /robots.txt. What you see tells you if the errors are happening now, keep coming back, or belong to an incident that's over.
Every HTTP status code starting with 5 signals a server-side failure.2 Google Search Console groups all of them under one status in the Page Indexing report: "Server error (5xx)."1 You'll find it under Indexing → Pages → Why pages aren't indexed.
Key takeaways:
- Find Google's failed request time in your logs before anyone changes a server setting.
- A healthy page now doesn't rule out an earlier or intermittent failure.1
- Already indexed pages stay in Google's index at first, but persistent server errors can lead to removal.3
- Check
/robots.txtseparately because its failure can stop crawling across the site.4
Pick your next move from the triage table below, and weigh urgency by how much the affected sections matter to the site.
| What you find | Priority and next action | Evidence to collect |
|---|---|---|
| Active failures across unrelated pages | Escalate to the hosting or infrastructure team | Failed requests, exact times, host status, resource graphs |
| The same routes fail repeatedly | Investigate the application or dependency behind those routes | App exceptions, database errors, recent deployments |
| A past failure with successful tests now | Check the incident record and monitor for recurrence | Crawl Stats request details and matching log entries |
/robots.txt returns a server error |
Restore access to that file promptly | Current response and Crawl Stats robots.txt availability |
What Google does with a 5xx, and how fast
Anything served with a 5xx status, Google just ignores. Google preserves already indexed URLs initially, then eventually drops them if server errors persist.3 One bad crawl, then, won't knock an indexed page out right away.
Crawl budget takes a hit.3 Google deliberately backs off crawling sites that return frequent server errors, since it's trying not to make your problem worse.5 And that slowdown hits the entire hostname, even pages that are serving content fine.
| Condition | Google's documented behavior | Practical response |
|---|---|---|
| Pages return 5xx | Google ignores the content; its crawlers slow down | Restore normal access; don't rely on the error content |
| Server errors persist | Already indexed URLs can eventually be dropped | Track repeat failures on the same pages |
| Pages return 503 or 429 | Googlebot retries for about two days; Google's troubleshooting guidance says returning these responses for more than two days causes those URLs to be dropped | Keep downtime brief and escalate if recovery is slipping |
| The server resumes 2xx responses | Google gradually increases crawling | Review later requests as well as current availability |
You'll see a two-day figure mentioned. It covers 503 and 429 responses, not every server error, and it isn't a recovery clock. For planned downtime, Google recommends limiting use of 503 to one or two days.6 Plan around that ceiling. It doesn't give you permission to leave a broken site alone for two days.
Pin down when it happened with Crawl Stats
The Page Indexing report identifies affected pages, but it isn't an outage clock. The report reflects Google's own crawl schedule, not the moment your server started failing.7 Search Console says collected data should normally be available in two to three days. Search your incident records by the time of the failed request. The day you happened to notice the status doesn't help.
You get to the Crawl Stats report through Settings → Crawl stats, in either a Domain property or a root URL-prefix property. Crawl Stats is available only for root-level properties.8 Working in a URL-prefix property for a subdirectory? Switch to a root-level one for this.
Read host status before the response breakdown
Host status distinguishes significant availability issues in the last week from older issues within the past 90 days.8 Click in and you'll see robots.txt availability, DNS resolution, and host connectivity. The Server connectivity graph is the useful one here: it marks the times your server didn't respond, or didn't send a full response, during a crawl.
Start with the affected period, then open By response → Server error (5XX). The thumbnail shows approximately when the errors occurred; opening the details gives exact times. Select an example request to see when Google fetched it, the HTTP status, and its size.8
Match requests to log files, not just URL counts
Crawl Stats response totals count requests, not unique URLs.8 The report records the actual requested URLs, but its examples are representative rather than exhaustive. Redirect hops count separately. These details explain why its examples can differ from the Page Indexing list.
The Page Indexing report provides overall totals but limits its example table to 1,000 rows.7 Neither list gives you the whole incident, which is why you want both. Get the failed request details into your worksheet first. Then go through the server, application, and CDN log files.
Server error investigation worksheet
Affected page:
Google request time and timezone:
Response recorded in Crawl Stats:
Host availability issues:
robots.txt response:
Current local test:
URL Inspection live test:
Matching web server / app / delivery log entry:
Recent deployment or configuration change:
Repeated elsewhere, or isolated:
Owner and next check:
Our guide to log file analysis for SEO goes deeper. Whoever owns the stack should trace that failed request through it. Hand them the log files that tie the "Server error (5xx)" status to one specific incident.
Which layer sent the error?
Google Search Console doesn't split these out individually in the Page Indexing report.1 Get the specific response from Crawl Stats request details or the incident logs. A code gives you a lead. Your logs confirm which layer actually failed.
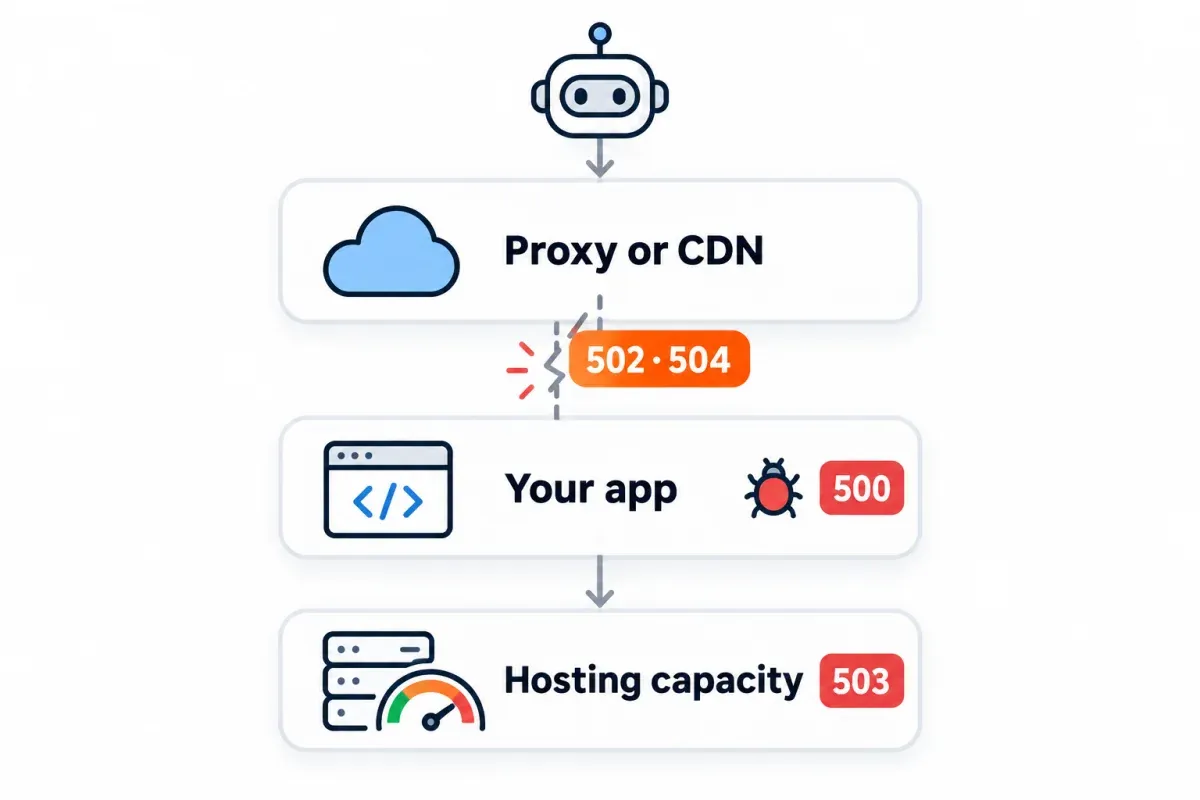
| Response | Meaning | Where to start |
|---|---|---|
| 500 Internal Server Error | An unexpected condition prevented the server from fulfilling the request | Application exceptions, CMS plugins or themes, recent changes |
| 502 Bad Gateway | A gateway or proxy received an invalid upstream response | Application process, origin address and port, intermediary logs |
| 503 Service Unavailable | Temporary overload or scheduled maintenance prevents the server from handling the request | Resource usage and maintenance configuration |
| 504 Gateway Timeout | A gateway or proxy didn't receive an upstream response in time | Slow queries, upstream services, timeout settings |
| 505 HTTP Version Not Supported | The server doesn't support, or refuses to support, the request's major HTTP version | Ask the server team to check protocol configuration |
Test the affected page without impersonating Google
Request the page by its full URL and look at the HTTP response you get now. Google uses this command format to confirm a maintenance response:
curl -I -X GET "https://www.example.com/affected-page"
curl -I -X GET "https://www.example.com/robots.txt"
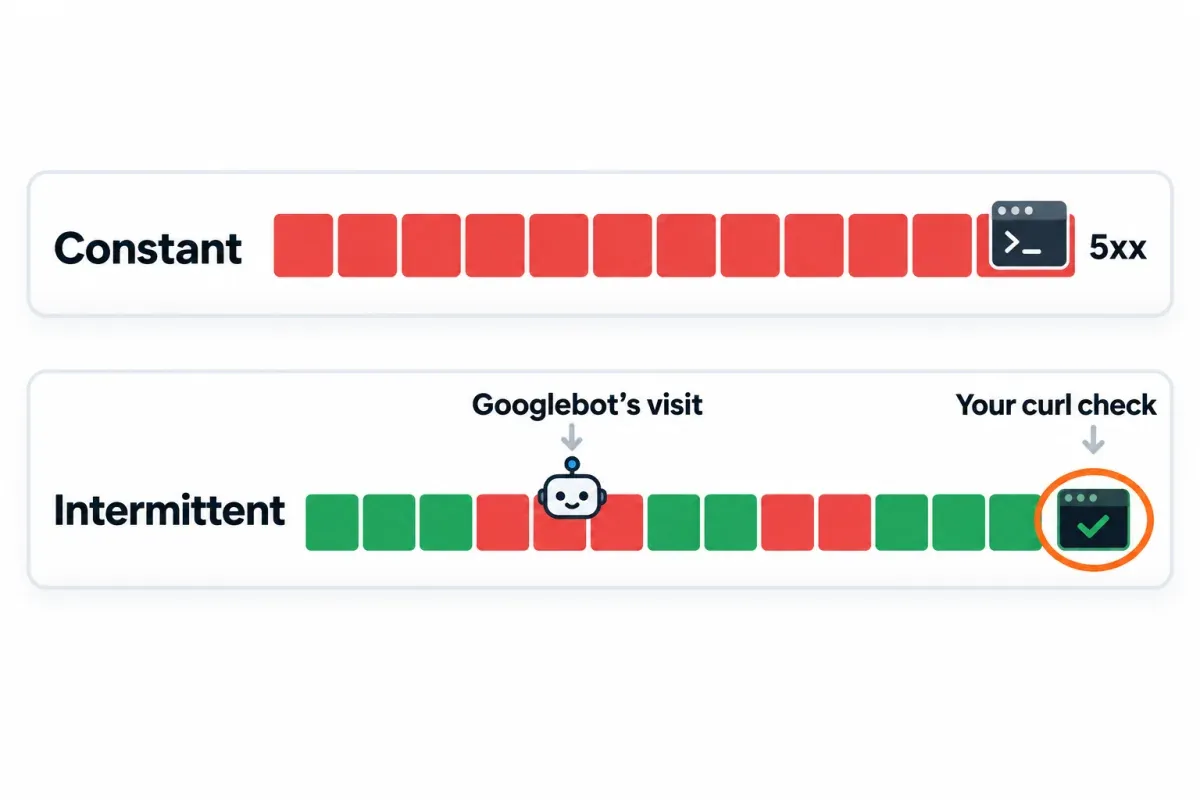
That request leaves from your network, not Google's, and no Googlebot user-agent string changes where it comes from. Server errors can be transient, so a successful local test or URL Inspection live test doesn't disprove Google's earlier failed crawl.1
App, hosting, and protection settings to check
Take the 500 Internal Server Error first. Read the application exception before you change anything unrelated. Recent deployments, database changes, plugin or theme updates: put the failure next to each and see what overlaps. A change that lines up with the failures gets rolled back, and it stays out until the bug is found.
With WordPress, your developer can switch suspect plugins off individually. Did the errors start after someone edited the web server config (.htaccess on Apache, say)? Look at that edit before anything else. If the failure isn't Googlebot-only, real visitors are seeing it as well, so write down which routes and actions break for them. If only Google's requests fail, check the protection settings below.
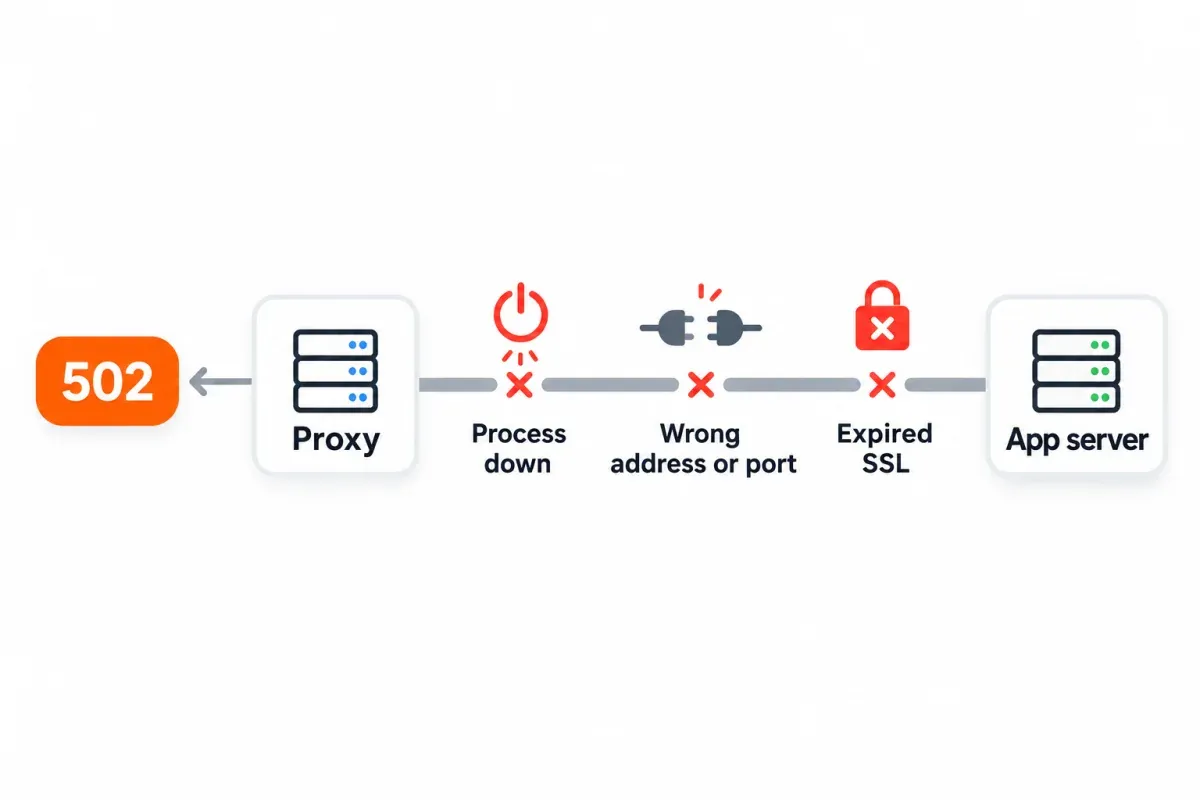
Then there's the 502 Bad Gateway. Here the first check is whether the app process is running and reachable from the gateway. The origin address, port, and certificate deserve a look as well, with intermediary logs compared against the app's. No entries in the app log? That means look wider. A quiet log isn't proof of a healthy app.
A 503 points you toward capacity or an intentional maintenance state.2 That makes CPU, memory, database connections, and the maintenance setup the places to check. With a 504 Gateway Timeout, slow database queries and upstream performance come before any timeout increase.
Google also lists hosting outages, overload, and misconfiguration as causes.1 No access to those systems? Send your hosting provider the incident details. Don't skip dynamic routes with long parameter lists, either. Google warns those can take too long to respond.
Your tests pass but Google's requests fail? Then DNS, the firewall, denial-of-service protection, and CMS settings are next. Googlebot can trigger protection systems because it often makes more requests than human users.1 The people running those systems can check the failed Google request against their own records.
Sometimes the test returns something else entirely, and then that's the issue to chase. Getting a 403 instead? Our "Blocked due to access forbidden (403)" guide covers that.
On Cloudflare, compare edge and origin responses
Cloudflare has its own 5xx server error codes.9 Pro, Business, and Enterprise plans get HTTP Traffic analytics, where you can filter by Edge status code or Origin status code. It's a companion to your logs. It doesn't replace them.
| Cloudflare response | Meaning | Investigation prompt |
|---|---|---|
| 520 | Web server returned an unknown error | Collect the error message and inspect origin and intermediary logs |
| 521 | Web server is down | Check origin availability |
| 522 | Connection timed out | Trace the connection between Cloudflare and the origin |
| 523 | Origin is unreachable | Review the origin connection and routing |
| 524 | A timeout occurred | Investigate the slow upstream operation |
| 525 | SSL handshake failed | Review origin SSL setup |
| 526 | Invalid SSL certificate | Check the origin certificate |
In particular, Cloudflare reports origin SSL problems as 525 or 526, so don't label them as 502 failures.9 Anything sitting between Cloudflare and the origin needs a look too: load balancers, caches, gateways, firewalls. The origin server's error logs might not show the cause at all.
When you write the ticket for your developer or host, give them evidence they can actually act on. Avoid a ticket that only says "Search Console has errors."
Subject: Investigate server errors on [hostname]
Affected URL(s):
Specific 5XX response and error message:
Failure time and timezone:
Crawl Stats request details:
Edge status / origin status, if available:
Relevant server and application log entries:
User experience: affected routes and failed actions:
Recent change to compare:
Current content and robots.txt test results:
Requested action: trace the failing layer and resolve the server errors
Verification: local test, Google live test, and later request/log review
When robots.txt is the URL returning 5xx
A server error on /robots.txt has a different scope from a failure on an article or product page. For the first 12 hours, Google stops crawling the site while retrying the robots.txt file.4 Check that file during any outage or maintenance test, even if the homepage loads.
For the next 30 days, Google uses its last good robots.txt version while retrying the file. If no cached version exists, Google assumes there are no crawl restrictions. After 30 days, Google behaves as if there is no robots.txt when the site is generally available; otherwise, it stops crawling the site.4
Timeouts and other network failures on robots.txt are treated as server errors too.4 The robots.txt availability chart in Crawl Stats' host status details shows when those fetches failed.8 Keep /robots.txt available during maintenance instead of returning the same 503 used for content pages.
Planned downtime: use 503 briefly and keep robots.txt available
For an urgent closure lasting one or two days, Google recommends an informational error page with a 503 response.6 Add a Retry-After header with a best-effort date or duration. Retry-After tells clients how long you expect the service to be unavailable.2
Return static HTML for the error message and test the deployed HTTP status. A maintenance page returned with 200 can be indexed as page content instead.3 For a longer closure, Google's guidance is to provide an indexable placeholder homepage returning 200.6
| Maintenance check | What to verify |
|---|---|
| Content page response | Actual 503, rather than a maintenance message returned with 200 |
| Retry-After header | Best-effort HTTP date or duration in seconds |
/robots.txt |
Available, rather than returning the maintenance 503 |
| Access and indexing settings | Don't replace the 503 with 403, 404, 410, noindex, or a site-wide robots.txt disallow |
| Length of closure | Plan to restore content within one or two days; use an indexable placeholder homepage for longer closures |
While a page returns 503, Google's systems cannot refresh its title, description, metadata, or structured data.6 Restore the content to fix the issue; editing the downtime message won't help. Recheck content routes and /robots.txt after deploying the rules.
Verify the fix without forcing a reindexing timeline
Repeat the local tests on affected routes and /robots.txt. Use URL Inspection's "Test Live URL" to confirm Google's own fetch succeeds, not just your own test.10 That result checks current access; compare later crawl requests and logs to look for recurring failures.
The Page Indexing report only updates after Google's next crawl of the affected URLs, so don't expect the status to clear immediately.1 Validation is optional: Google also updates the issue count when it crawls a page with a known issue. In the Page Indexing report, Validate fix checks all instances of that issue; filtering to a sitemap limits validation to that subset.
Google Search Console validation typically takes up to about two weeks, but it can take much longer.1 Validation stops when Google finds a remaining instance. This is a validation timeframe, not a promise that clicks, rankings, or crawl rate recover by the same deadline.
A working server again is no reason to bump the <lastmod> dates in your sitemap. Those dates are meant for real page updates, like changes to the main content, structured data, or links. Keep those dates tied to what actually changed on the pages.
URL Inspection's Request indexing action has a daily limit.10 You can use it for a few key pages; it isn't a recovery plan for an outage. Keep server access stable and let later crawls confirm the repair.
Fix verification checklist
[ ] Affected content pages return their normal successful response
[ ] robots.txt is available
[ ] URL Inspection live test succeeds
[ ] Later logs and Crawl Stats show no repeat of the same failure
[ ] Page Indexing issue count is checked after recrawling
[ ] Optional validation covers the intended report or sitemap subset
[ ] Sitemap lastmod dates still reflect significant page changes
Prevent recurrence and choose what to watch
For "Server error (5xx)", use uptime alerts for operations and Search Console for what Google encountered. Search Console helps you diagnose. It's a poor outage alarm, though. For alerts, choose representative pages from the affected sections and send yourself a test alert before trusting the setup.
| Tool | Setup and alerts | Choose it when |
|---|---|---|
| Better Stack | Hosted monitoring; its free personal-project plan includes 10 monitors and heartbeats, one status page, and Slack and email alerts. Phone and SMS alerts require a paid Responder license | You prefer a hosted service |
| Uptime Kuma | Free, MIT-licensed, self-hosted software with HTTP(s), DNS, and other monitors; supports 20-second intervals and notifications through Slack, email, Telegram, Discord, and other services | You can operate the monitoring service yourself |
Add alerts on CPU, memory, and database connection usage alongside them. Roll releases out in stages and check that your downtime rules really deployed. After an incident, go over anything that failed again. The homepage alone isn't a watch list; add every newly affected route.
SEO Heatmap helps pick those pages by putting Search Console clicks for every page side by side. Begin with the pages already pulling search traffic, then add a few from each section you want covered.
Frequently asked questions
What is Google Search Console's "Server error (5xx)" status telling me?
It says Googlebot asked for the page and got a 500-level error from your server in return. Read the host status verdict in Crawl Stats before anything else, and after that test /robots.txt plus an affected page. Then tie the failed request to your incident logs.
The page loads for me, so why is Search Console showing a server error?
Server errors are often intermittent. Your clean test today says nothing about the request Google saw fail earlier. Match the exact request time in Crawl Stats against your server, application and delivery logs. Check what happened in that window, deployments or resource usage for example, rather than assuming it fixed itself.
Where can I find the exact 5xx code Google received?
In Crawl Stats, go to By response → Server error (5XX) and click any example request. You'll see the HTTP status there, plus the time Google fetched it. The Page Indexing report won't help with that, since it lumps every server error into one status. Diagnose from request details and the matching logs.
How do I fix the server error behind the Search Console status?
Look at host status first. Then pick a single failed request, since its details show which server layer is to blame. For a 500 that means application exceptions; for a 504, slow upstream operations. Once it's fixed, repeat the local tests and the URL Inspection live test. Later requests will show if the error returns.
Can a server error remove pages that are already indexed?
Yes, persistent server errors can lead to removal, but Google preserves already indexed URLs initially. For 503 or 429 responses, Googlebot retries for about two days. Google's troubleshooting guidance says returning those responses for more than two days causes the affected URLs to be dropped from its index.
What separates a 502 from a 504 when diagnosing?
In a 502, a gateway or proxy got back an invalid response from upstream. A 504 is a timeout, with no upstream response arriving in time. So a 502 points you at the app process and its connection, and a 504 at slow queries or upstream services.
What if the server error affects robots.txt too?
For the first 12 hours, Google stops crawling the site and keeps retrying robots.txt. After that, and for 30 days, it falls back on the last good version. If it has no cached copy, it acts as if there are no crawl restrictions. Get the file back up fast, and don't let it share the maintenance responses you use for content pages.
How long until the status clears, and do I need Validate fix?
The issue count updates when Google recrawls affected pages, and validation is optional. Validate fix in the Page Indexing report checks every instance of the issue, unless you filter to a sitemap, which limits it to those URLs. Expect up to about two weeks, sometimes much longer, and know that it stops as soon as Google finds an instance that's still broken. Clicks and crawl rate run on their own timeline.
After restoring access, use SEO Heatmap to compare click trends across site sections and watch whether search traffic returns. It is free for one Search Console property, so you can follow the affected sections alongside your server checks.
Sources (10)
SEO Heatmap Knowledge relies on primary sources: Google's documentation, web standards, peer-reviewed research, and vendors' own pages for their pricing and features. Our editorial standards
- Search Console Help. “Page indexing report.”
- IETF. “HTTP Semantics.”
- Google Crawling Infrastructure. “How HTTP status codes affect Google's crawlers.”
- Google Crawling Infrastructure. “How Google interprets the robots.txt specification.”
- Google Search Central. “Troubleshoot Google Search crawling errors.”
- Google Search Central. “Temporarily pause or disable a website.”
- Search Console Help. “About Search Console data.”
- Search Console Help. “Crawl Stats report.”
- Cloudflare. “Error responses.”
- Search Console Help. “URL Inspection tool.”

